OpenAI's flagship image model with strong prompt fidelity, crisp text rendering, and instruction-based editing across up to 16 reference images.
 OpenAI Image Generation Released Apr 21, 2026 Proprietary Endpoint
OpenAI's flagship image model with strong prompt fidelity, crisp text rendering, and instruction-based editing across up to 16 reference images.
Also known as OpenAI GPT Image 2
gpt-image-2/v1/images/generationsopenai/gpt-image-2Outputs from our published tests. Each one links to the post it comes from.
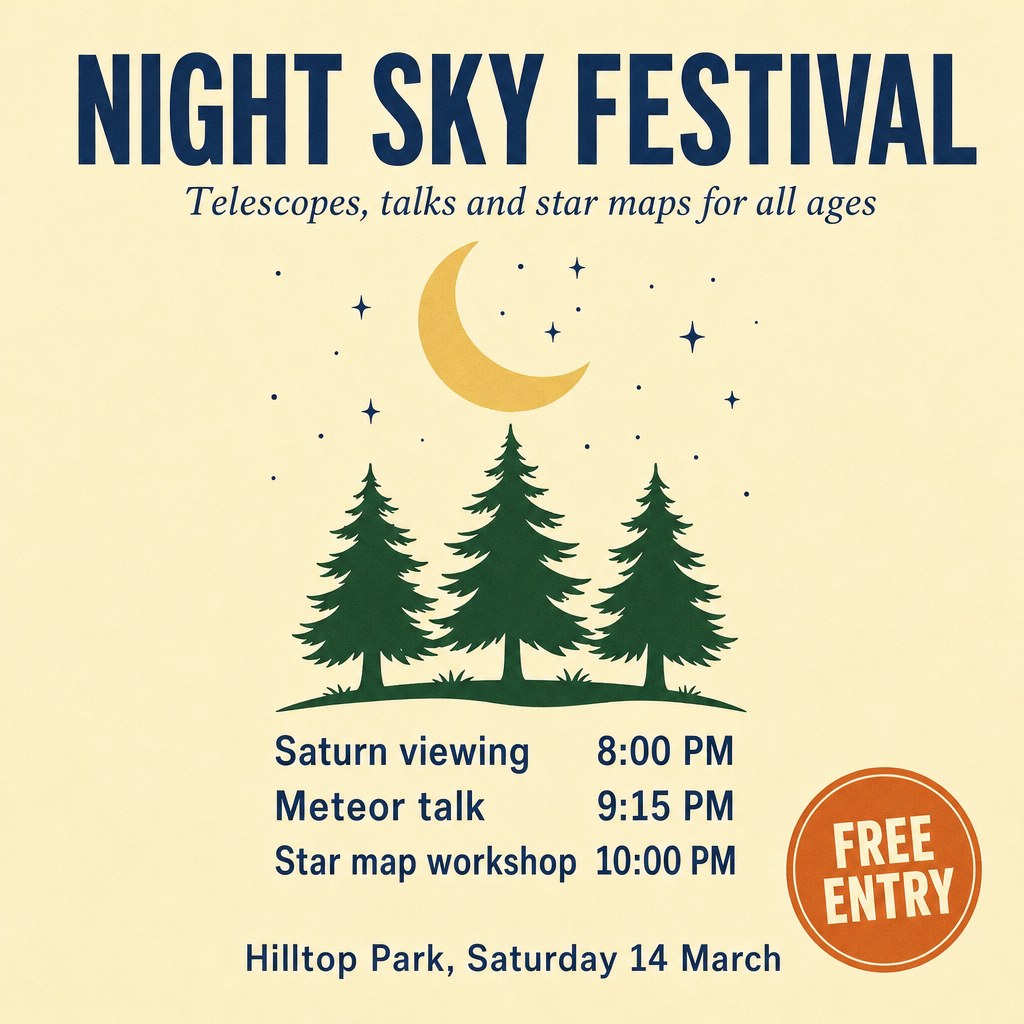
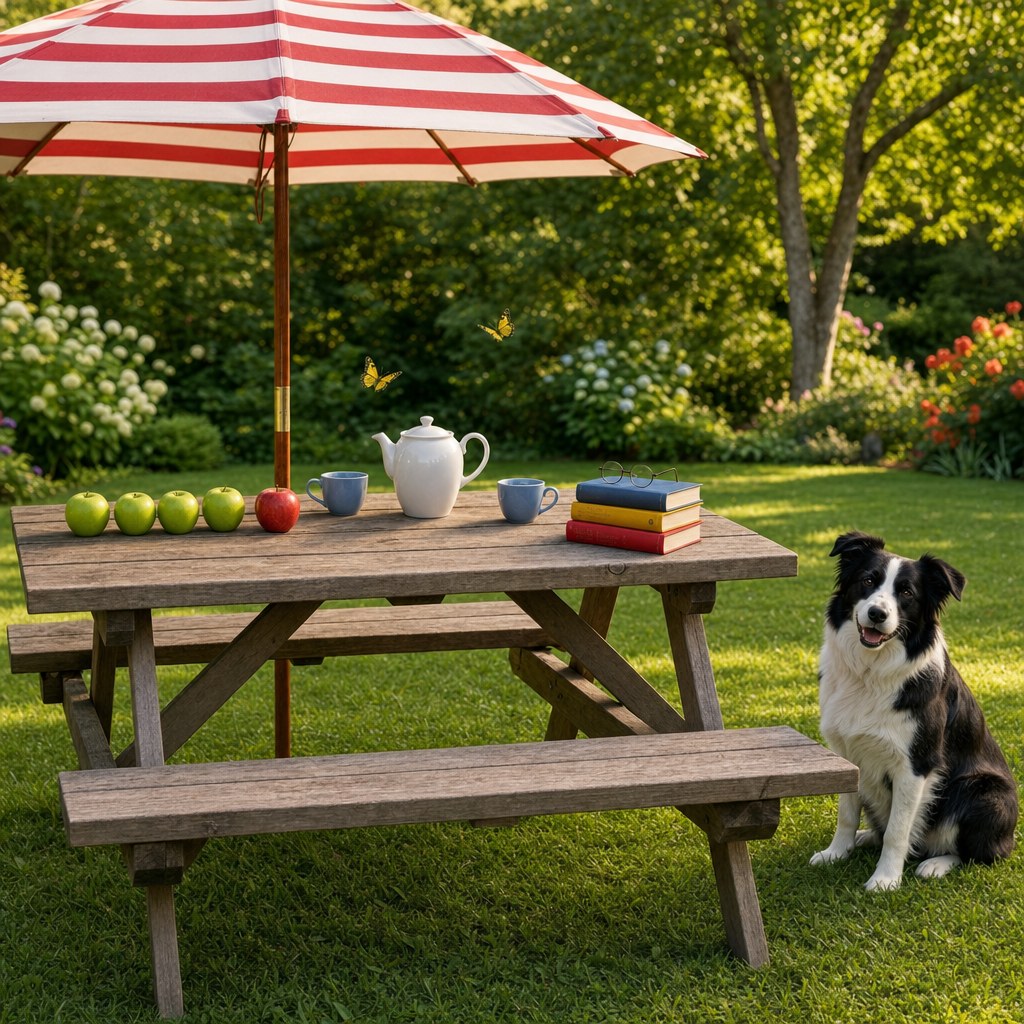
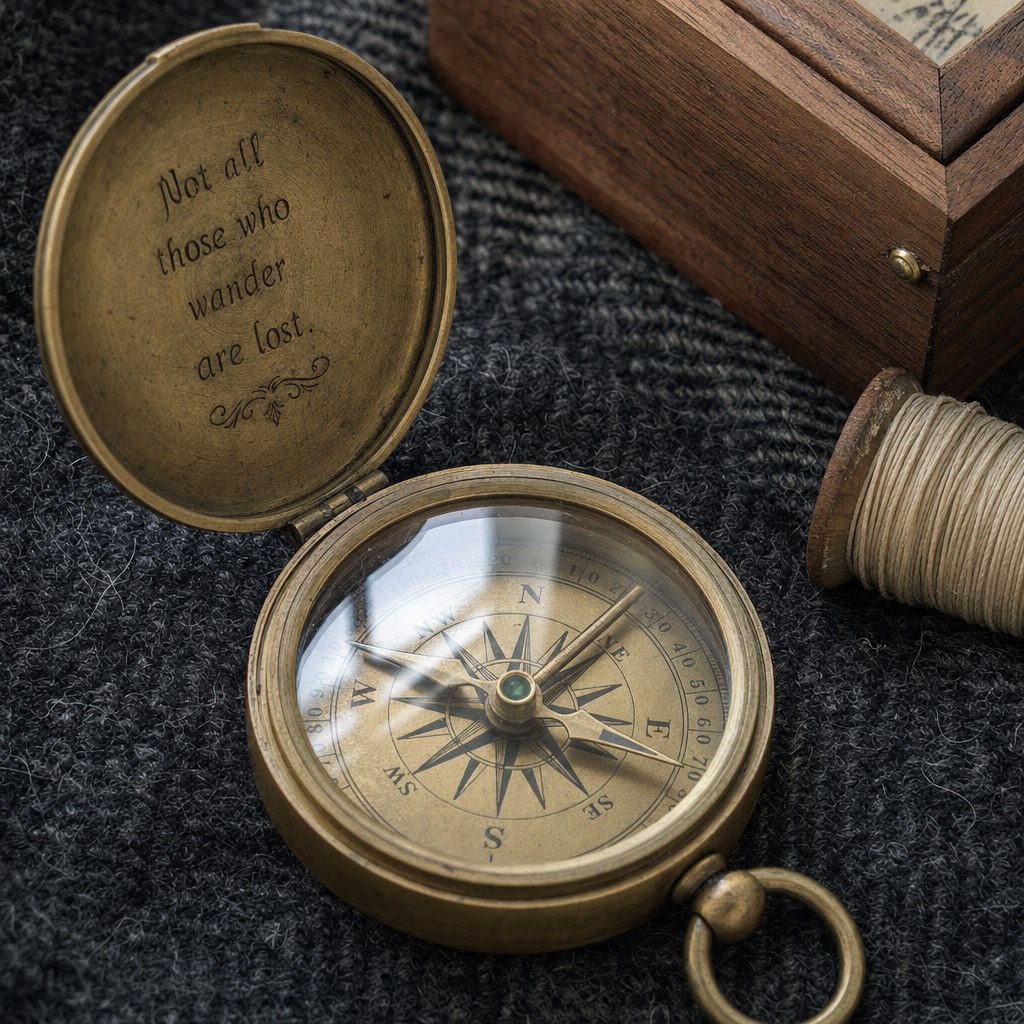
From Seedream 5.5 vs Seedream 5.0 Pro vs GPT Image 2 vs Qwen Image 2.1: three prompts
Live pay-as-you-go rates from the EmpirioLabs catalog. You can also choose a plan with weekly allowances.
GPT Image 2 runs through POST /v1/images/generations. The request returns a job_id right away; poll GET /v1/jobs/{job_id} until the job completes and read the output URLs from the result. Or add "sync": true to skip polling: the request stays open and returns the finished OpenAI-style image response directly, so OpenAI SDKs work as-is. Get an API key from the EmpirioLabs dashboard.
curl https://api.empiriolabs.ai/v1/images/generations \
  -H "Authorization: Bearer $EMPIRIOLABS_API_KEY" \
  -H "Content-Type: application/json" \
  -d '{
    "model": "gpt-image-2",
    "prompt": "Describe what you want GPT Image 2 to generate."
}'curl https://api.empiriolabs.ai/v1/jobs/JOB_ID \
-H "Authorization: Bearer $EMPIRIOLABS_API_KEY"import requests
response = requests.post(
"https://api.empiriolabs.ai/v1/images/generations",
headers={"Authorization": "Bearer YOUR_EMPIRIOLABS_API_KEY"},
json={
"model": "gpt-image-2",
"prompt": "Describe what you want GPT Image 2 to generate.",
},
)
job = response.json()
# Generation runs as an async job. Poll until it completes.
import time
while True:
status = requests.get(
f"https://api.empiriolabs.ai/v1/jobs/{job['job_id']}",
headers={"Authorization": "Bearer YOUR_EMPIRIOLABS_API_KEY"},
).json()
if status.get("status") in ("completed", "failed"):
print(status)
break
time.sleep(5)Request parameters supported by the GPT Image 2 API on EmpirioLabs. Defaults apply when a field is omitted.
| Parameter | Type | Default | Range / values | Description |
|---|---|---|---|---|
| prompt | string | - | - | Text prompt. With input images attached, becomes an editing or compositing instruction. |
| quality | enum | medium | low, medium, high | Rendering quality tier. Higher tiers produce more detail and cost more per image. |
| size | enum | 1024x1024 | 1024x1024, 1536x1024, 1024x1536 | Output resolution: square, landscape, or portrait. |
| image | array | - | - | Up to 16 input image URLs for editing or multi-reference composition. |
| num_images | number | 1 | 1 to 4 | Number of images to generate. Each is billed separately. |
| moderation | enum | auto | auto, low | Content filtering strictness applied by the model service. |
| response_format | enum | url | url, b64_json | Return signed URLs or base64 image data. |
Quality tiers Low, Medium, and High set the rendering fidelity and the per-image price. Output sizes are 1024x1024, 1536x1024, and 1024x1536. Attach up to 16 images to edit or composite them, with the prompt as the instruction.
Announcements, prompt tests, and comparisons that cover this model.
On EmpirioLabs, GPT Image 2 is billed pay as you go: Low $0.012 per image; Medium $0.106 per image; High $0.422 per image. You can also choose a plan with weekly allowances. The live rate card on this page always matches what the API charges.
GPT Image 2 takes Text, Image as input and returns Image.
GPT Image 2 is served through POST /v1/images/generations on api.empiriolabs.ai with standard bearer-token authentication.
Send gpt-image-2 as the model in your request. The alternate IDs openai/gpt-image-2 also work.
OpenAI released GPT Image 2 on Apr 21, 2026.
Yes. The EmpirioLabs playground runs GPT Image 2 in the browser with the same parameters the API exposes, so you can test prompts before writing code.
Create an EmpirioLabs account, then generate a key under API Keys in the dashboard. Billing is pay-as-you-go credits, so you only pay for the requests you make. You can also choose a plan with weekly allowances.
Check out our pricing or reach out if you want your own model deployed on our stack.