Disclosure: This article was written with AI assistance and reviewed by EmpirioLabs AI.
LightOnOCR-3 4B is available on EmpirioLabs. It is LightOn's document OCR model: send a PDF or an image, and it returns each page as Markdown, with the text in reading order, headings, lists, tables, math in LaTeX, and charts as tables of their data points. Each page also comes back with its layout: the type and position of every block on the page. It runs on POST /v1/ocr, in the API and in the Playground.
Benchmark. LightOn reports an overall olmOCR-Bench score of 86.3 for LightOnOCR-3 4B in its release announcement of October 8, 2026.
What it reads
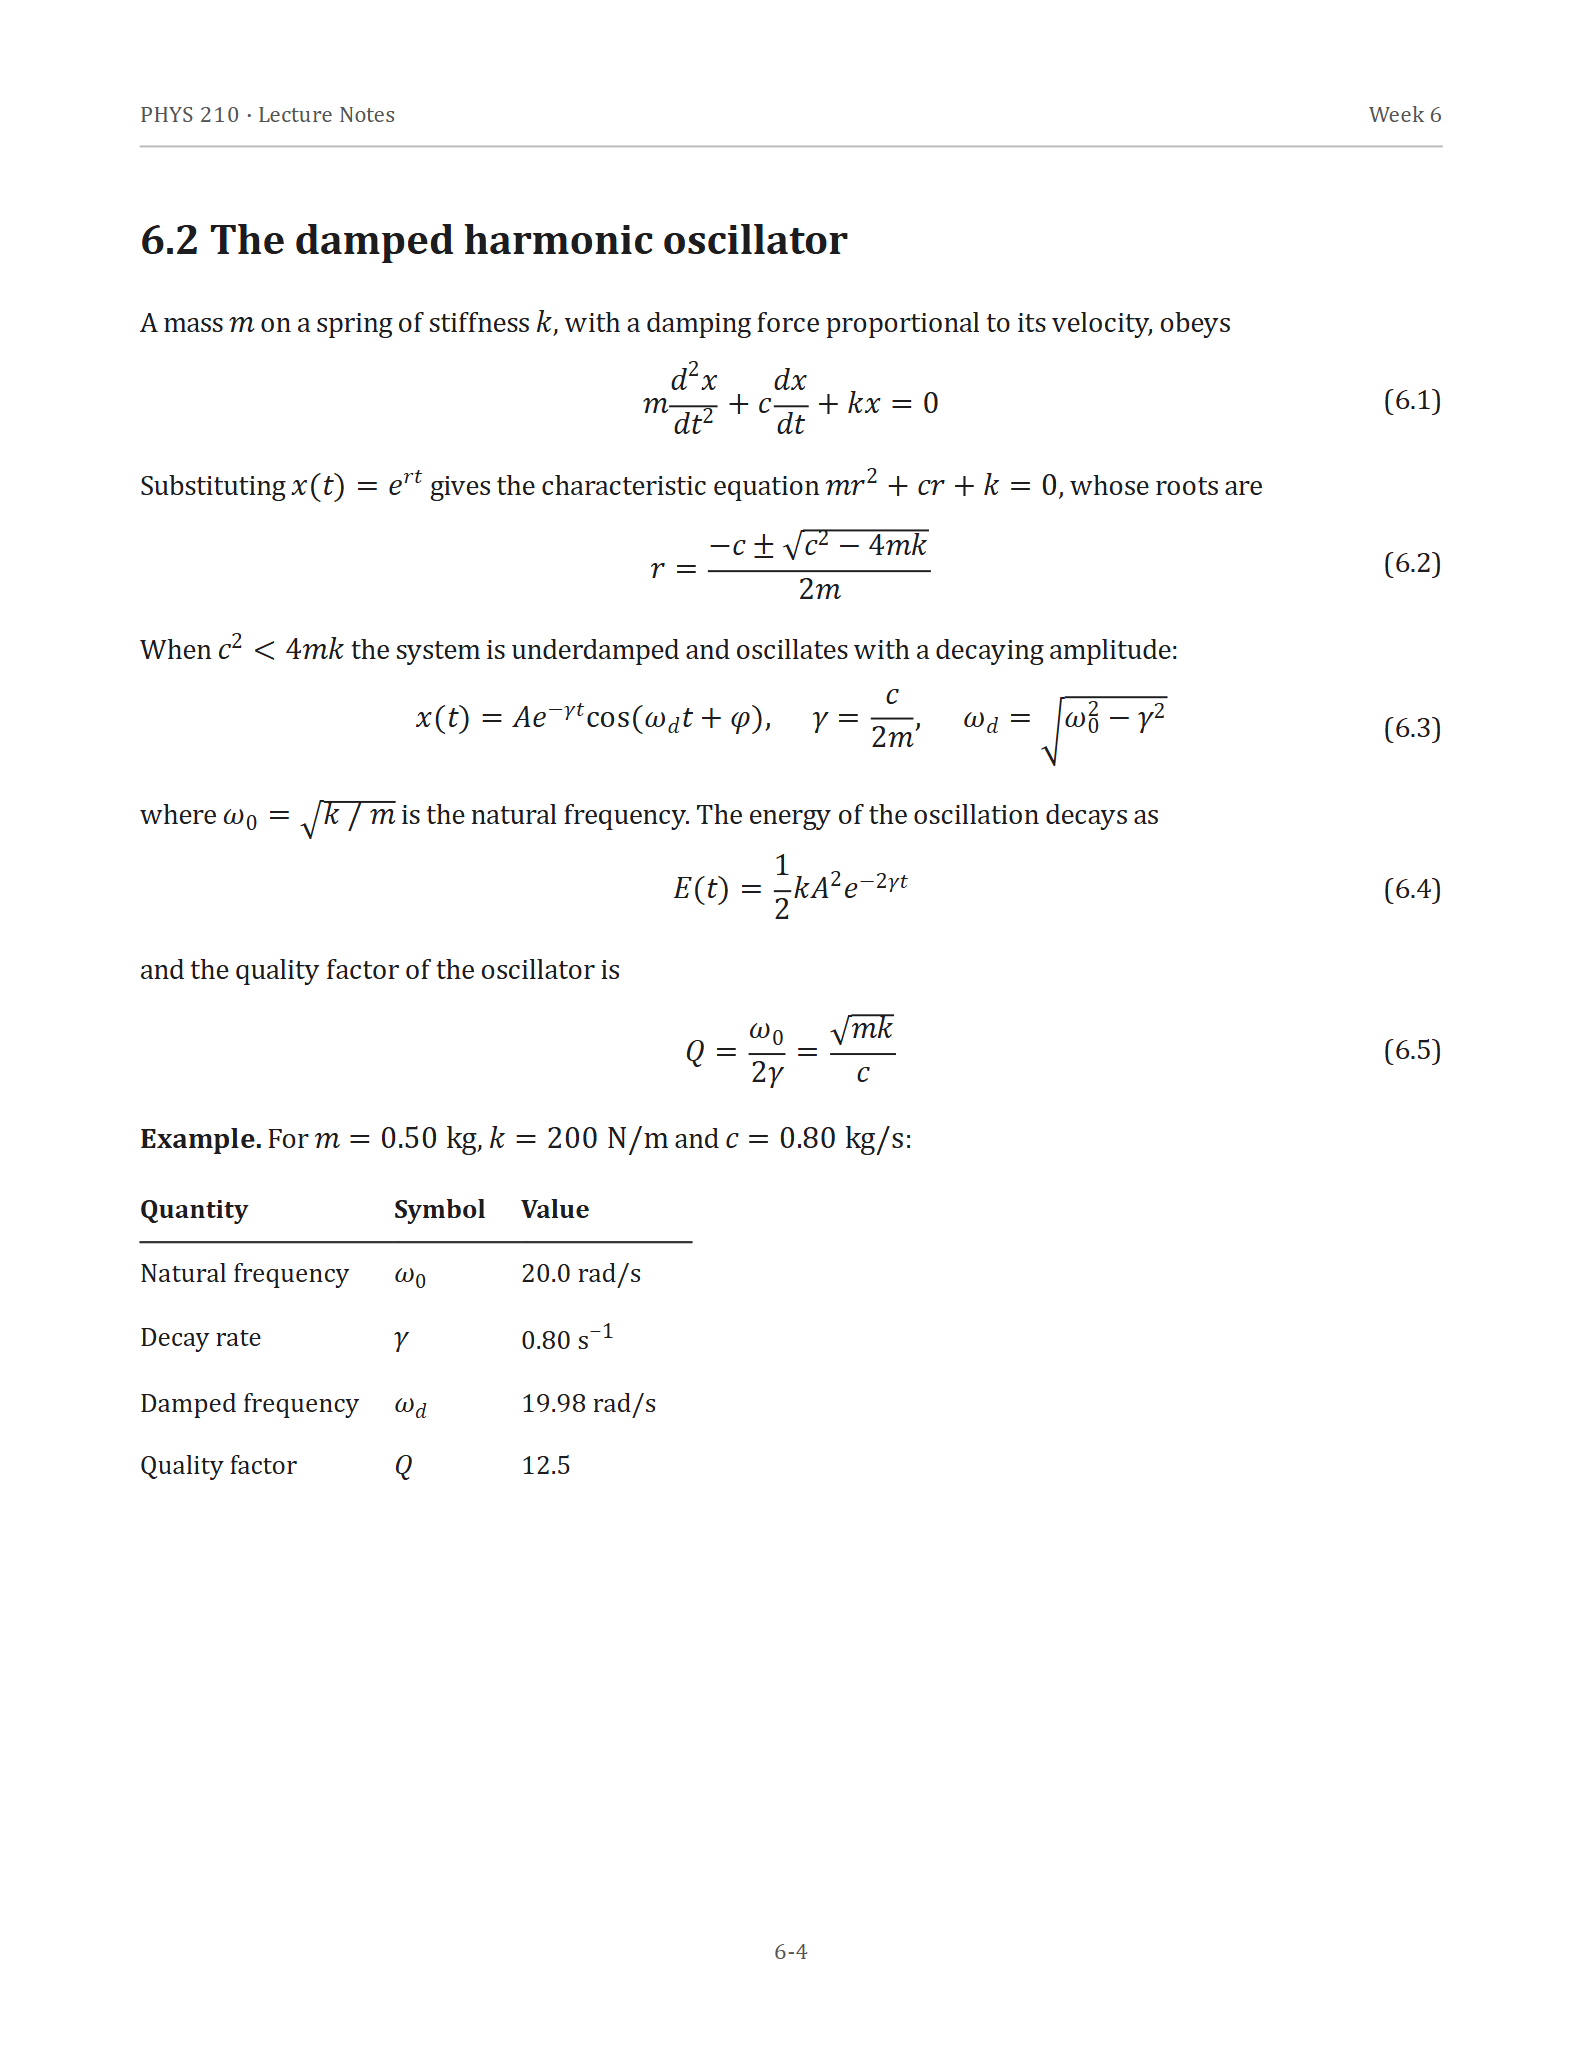
A test page of lecture notes, read in one request. This page and two more against three vision chat models are in LightOnOCR-3 4B vs Qwen3.5 4B vs Gemma 4 26B-A4B vs Mistral Small 3.1.
The start of the Markdown it returned for that page; the other three equations, the table, and the page number follow in the same response:
PHYS 210 · Lecture Notes

Week 6

## 6.2 The damped harmonic oscillator

A mass $m$ on a spring of stiffness $k$ , with a damping force proportional to its velocity, obeys

$$
m \frac{d^2 x}{dt^2} + c \frac{dx}{dt} + kx = 0 \quad \text{(6.1)}
$$

Substituting $x(t) = e^{rt}$ gives the characteristic equation $mr^2 + cr + k = 0$ , whose roots are

$$
r = \frac{-c \pm \sqrt{c^2 - 4mk}}{2m} \quad \text{(6.2)}
$$
Your first request
Send a document by URL or as a base64 data URI. This request reads the first two pages of a sample PDF:
curl https://api.empiriolabs.ai/v1/ocr \
  -H "Authorization: Bearer $EMPIRIOLABS_API_KEY" \
  -H "Content-Type: application/json" \
  -d '{
    "model": "lightonocr-3-4b",
    "document": {
      "type": "document_url",
      "document_url": "https://media.empiriolabs.ai/assets/blog-images/lightonocr-3-4b-test-2026-10-25/sample-document.pdf"
    },
    "pages": [0, 1]
  }'
A file on your machine goes in as a data URI, with no hosting needed:
import base64
import os

import requests

with open("report.pdf", "rb") as handle:
    encoded = base64.b64encode(handle.read()).decode()

response = requests.post(
    "https://api.empiriolabs.ai/v1/ocr",
    headers={"Authorization": f"Bearer {os.environ['EMPIRIOLABS_API_KEY']}"},
    json={
        "model": "lightonocr-3-4b",
        "document": {"type": "document_url", "document_url": f"data:application/pdf;base64,{encoded}"},
    },
    timeout=300,
)
response.raise_for_status()
for page in response.json()["pages"]:
    print(f"--- page {page['index']} ---")
    print(page["markdown"])
An image works the same way, with "type": "image_url" and the URL or data URI in image_url. A document can be a PDF or a PNG, JPEG, WebP, TIFF, BMP, GIF, or AVIF image of up to 50 MB, and one request reads up to 1,000 pages.
What comes back
The response holds one object per page in pages. Each has the page as markdown; blocks, every region of the page in reading order with its type (title, text, list, table, equation, caption, header, footer, and others) and its box in pixels; images, the image regions; and dimensions, the size of the page image the boxes refer to. usage_info.pages_processed counts the pages read. One of the 16 blocks returned for the lecture-notes page:
{
  "type": "equation",
  "top_left_x": 641,
  "top_left_y": 526,
  "bottom_right_x": 1447,
  "bottom_right_y": 610,
  "content": "$$\nr = \\frac{-c \\pm \\sqrt{c^2 - 4mk}}{2m} \\quad \\text{(6.2)}\n$$"
}
A request answers when its pages are read. One still running after about four and a half minutes answers 202 with a job_id: poll GET /v1/jobs/{job_id} until status is completed, and the pages are in result. To get the job id at once, send the header Prefer: respond-async.
Options
- Pages.
pagestakes zero-based page numbers as a list ([0, 2, 3]) or a string ("0,2-4"). Leave it out to read every page. - Tables.
table_formatset tomarkdownorhtmlmoves each table intotablesin that format and leaves a link such as[tbl-0.html](tbl-0.html)in the page Markdown. Without it, tables stay in the Markdown as HTML. - Images.
include_image_base64returns each image region as a JPEG data URI.image_limitcaps how many images come back for the whole document, andimage_min_sizeleaves out regions narrower or shorter than that many pixels. - Headers and footers.
extract_headerandextract_footermove them out of the Markdown into their own fields. - Layout.
include_blocksset tofalseleavesblocksout.
Operational notes
- Page numbers start at 0.
"pages": [1]reads the second page. - Dollar signs can come back escaped. In page text a dollar sign may read
\$, and inside HTML tables$. Unescape the Markdown before you search it for amounts. - Annotation fields are refused.
bbox_annotation_format,document_annotation_format, anddocument_annotation_promptanswer400before any page is read.
Pricing
Billed per page read. Each request is billed at least 5 pages, so send a long document as one PDF rather than one request per page. A request that fails is not billed for pages it did not return. Current rates are on the model page and the pricing page.
Start building
Try LightOnOCR-3 4B in the Playground with your own document, and read the Document OCR guide and the API documentation for every parameter.