Aplomb 1 is our first model. It takes text, JSON, images, audio and video in a single request, reads up to 1M tokens, and makes a decision on a 1M-token document in about 3 seconds. A short question takes about 15 ms of model time.
It runs on an inference runtime we built for decision models. On our API and in the Playground, long documents go through fast long-context mode: a 1M-token document takes about 3 seconds instead of 111, and fast mode answered all 525 decisions in our long-context tests correctly.
For agents, Aplomb 1 returns a probability for every tool and for each enum and boolean argument in one request, so an agent acts when the model is sure and escalates when it is not. Every answer is calibrated, and it can say when the input does not hold the answer instead of guessing. It is built for the decisions software makes thousands of times a day, from routing a ticket to picking an agent's next tool.
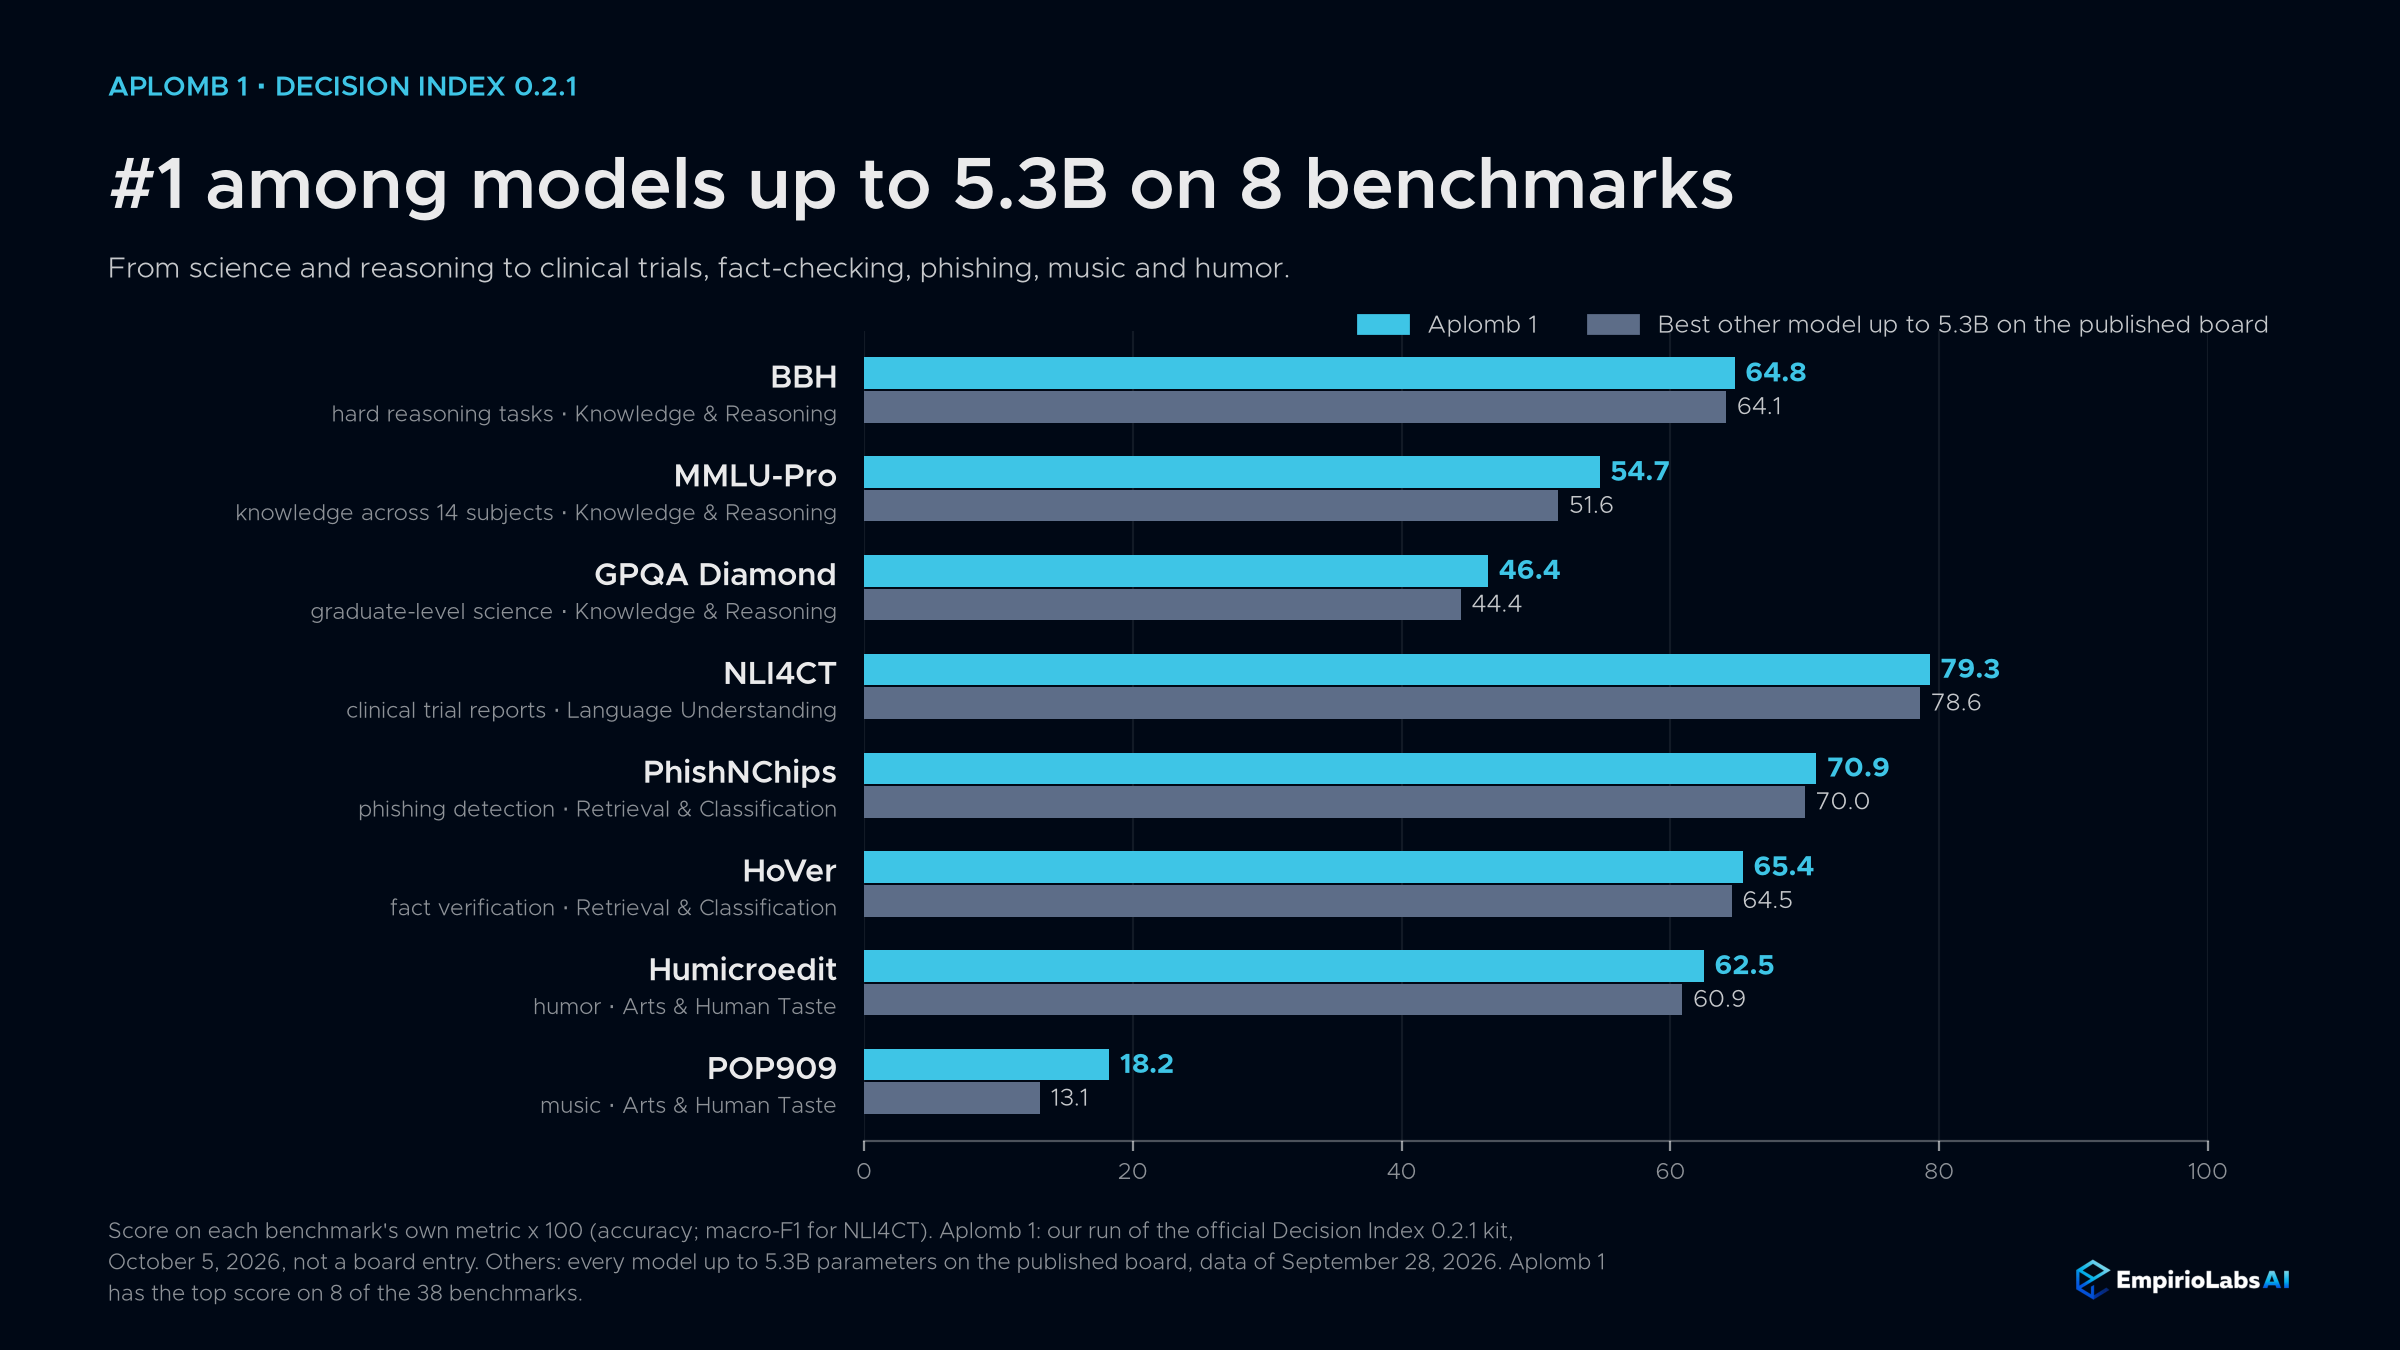
As of October 6, 2026, it is #1 among 4B models on the published Decision Index board, with 44.86 on our run of the official kit, and #1 among models up to 5.3B parameters on 8 of the 38 benchmarks. It is available today in the EmpirioLabs API and Playground, and its weights are on Hugging Face under the EmpirioLabs Model License.
| Aplomb 1 at a glance | |
|---|---|
| Inputs | Text, JSON, images, video and audio, in any mix |
| Window | 1,000,000 tokens of state plus question |
| Questions | Yes or no, choice (2 to 255 options), score (2 to 10 levels), tool selection |
| Not in the state | A probability that the input does not hold the answer |
| Tool selection | The next tool to call, with probabilities for its enum and boolean arguments |
| Speed | About 15 ms of model time for a short question; about 3 seconds for a 1M-token document in fast long-context mode |
| API formats | The Decisions API, plus the OpenAI, Anthropic and Gemini formats |
| Billing | Input tokens only; output tokens are always zero |
| Data retention | Zero data retention by default |
| Size | 5.3 billion parameters, built on Qwen3.5-4B; open weights on Hugging Face |
| Decision Index 0.2.1 | 44.86 on our run of the official kit, #1 among 4B models on the published board as of October 6, 2026 |
What it answers
Four question types. noul answers yes or no with the probability of yes. choice picks one of 2 to 255 options and returns the full distribution. score places the state on an ordered scale of 2 to 10 levels. tool picks which of your function tools to call and returns distributions over its enum and boolean arguments.
Not in the state. Add "abstain": true to a question and the answer also carries the probability that the state does not contain what the question needs. A record with no carrier field gets a high abstain probability instead of a confident guess.
Independent answers. Up to 128 questions share one state, and each is answered on its own, so adding a question never changes another answer.
Tool selection for agents
Give Aplomb 1 your agent's function tools and the current state (a ticket, a conversation, a record), and it returns the tool to call next with a probability for every tool and a distribution for each enum and boolean argument, in one request. A general LLM writes a tool call out token by token and does not say how sure it is about the tool or any argument. The agent acts when the probability is high and hands the step to a larger model when it is not, so routine steps skip a generated answer. We found no other decision model that returns argument probabilities.
A ticket that reads "Order B-44120 arrived with a cracked screen. I want my money back." with three tools, issue_refund (a reason enum and a full_refund boolean), track_package and escalate_to_human, comes back as (abridged, rounded):
{"tool": "issue_refund",
 "probabilities": {"issue_refund": 0.969, "none": 0.025, "escalate_to_human": 0.005, "track_package": 0.002},
 "arguments": {"issue_refund": {
   "reason": {"value": "damaged", "probabilities": {"damaged": 0.993, "not_as_described": 0.007, "late": 0.001}},
   "full_refund": {"value": true, "probability_true": 0.761}}},
 "open_arguments": {"track_package": ["order_id"]}}
Free-text arguments, such as an order id, are listed under open_arguments for the agent to fill.
Mixed inputs, up to 1M tokens
Text, JSON objects and arrays, images, video and audio go into the same state, in any combination: a support call recording next to the account record, a dashcam clip next to the claim form, a product photo next to the listing. The state plus the longest question can run to 1,000,000 tokens, enough for a long contract bundle, a year of tickets or hours of transcripts in one request.
How it scores
We ran Aplomb 1 and three open 4B decision models on the same items, and set the numbers Intern-Decision published for Jev, JevK5 and SemIf next to them. On the seven-suite bundle Intern-Decision reports, Aplomb 1 averages 88.7%. Against Jev's published row it is ahead on JevBench Hard and typed decisions, level on JevBench Easy, and behind on JevBench Original, ToolACE, AG News and WildJailbreak. Its largest lead is on JevBench Hard, +5.4 points.
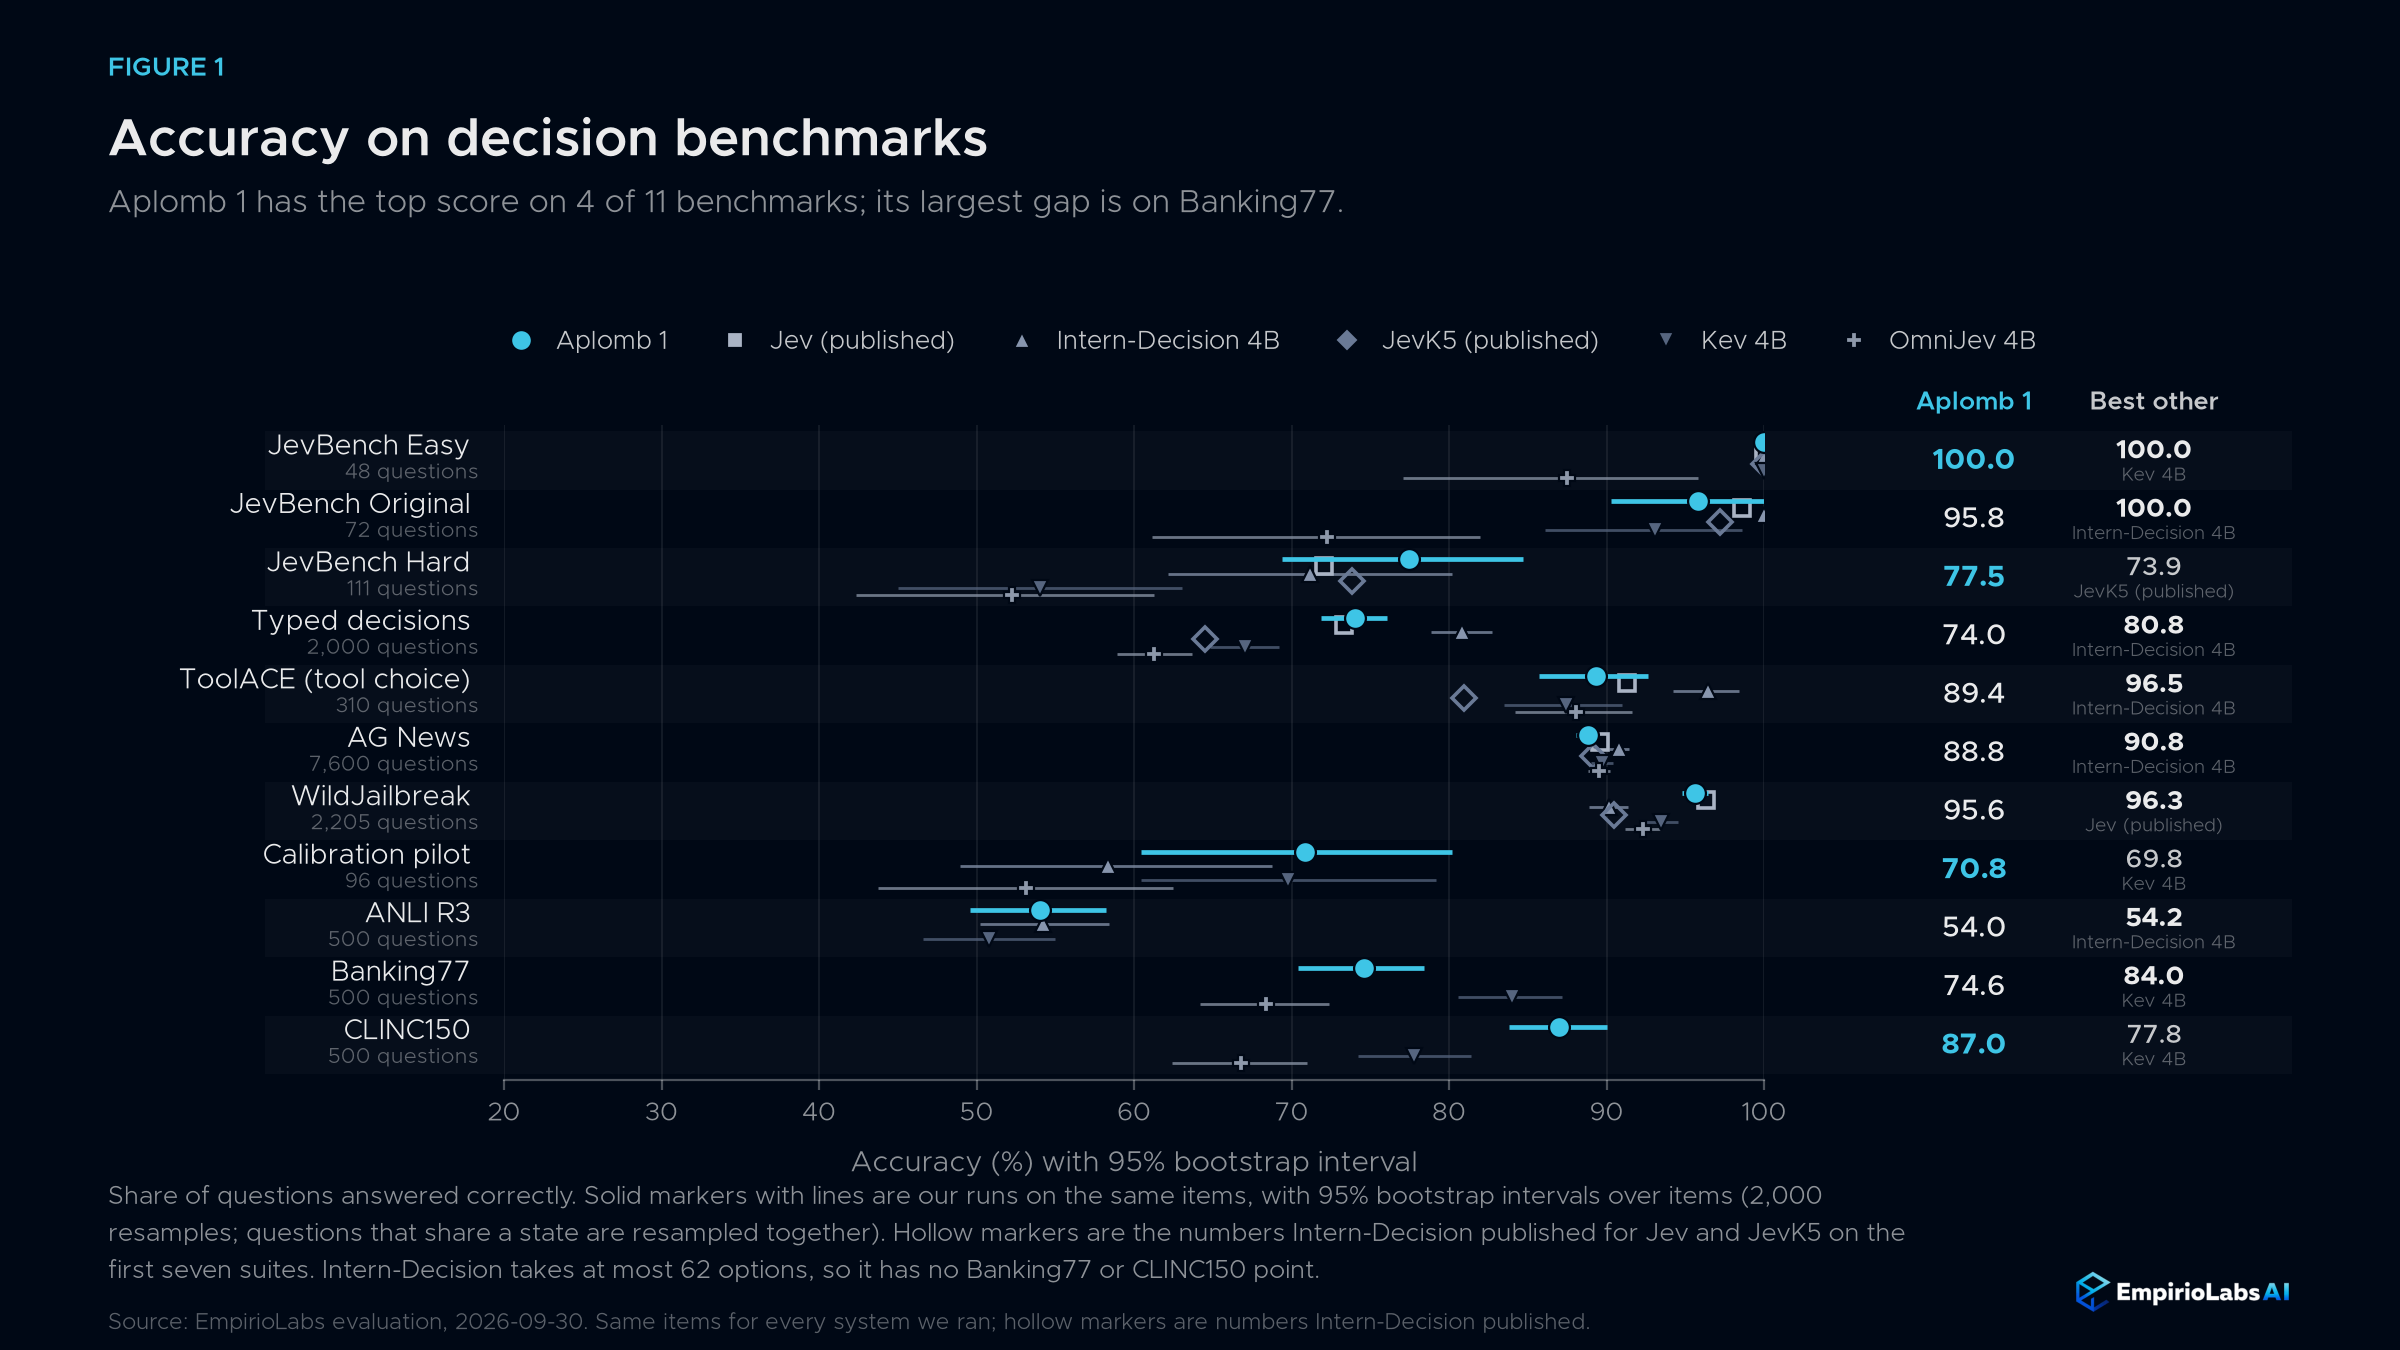
| Benchmark | Aplomb 1 | Jev (p) | JevK5 (p) | SemIf (p) | Intern-Decision 4B | Kev 4B | OmniJev 4B |
|---|---|---|---|---|---|---|---|
| JevBench Easy | 100.0 | 100.0 | 100.0 | 100.0 | 100.0 | 100.0 | 87.5 |
| JevBench Original | 95.8 | 98.6 | 97.2 | 98.6 | 100.0 | 93.1 | 72.2 |
| JevBench Hard | 77.5 | 72.1 | 73.9 | 61.3 | 71.2 | 54.1 | 52.3 |
| Typed decisions | 74.0 | 73.3 | 64.5 | 62.8 | 80.8 | 67.0 | 61.3 |
| ToolACE | 89.4 | 91.3 | 81.0 | 85.2 | 96.5 | 87.4 | 88.1 |
| AG News | 88.8 | 89.6 | 89.1 | 89.2 | 90.8 | 89.7 | 89.6 |
| WildJailbreak | 95.6 | 96.3 | 90.5 | 92.5 | 90.2 | 93.5 | 92.3 |
| Average | 88.7 | 88.7 | 85.2 | 84.2 | 89.9 | 83.5 | 77.6 |
(p) As published by Intern-Decision for the same items. Intern-Decision reports 90.02 for its 4B model on this bundle; the column shows our run.
| Benchmark | Aplomb 1 | Intern-Decision 4B | Kev 4B | OmniJev 4B |
|---|---|---|---|---|
| Calibration pilot | 70.8 | 58.3 | 69.8 | 53.1 |
| ANLI R3 | 54.0 | 54.2 | 50.8 | n/a |
| Banking77 (77 options) | 74.6 | n/a | 84.0 | 68.4 |
| CLINC150 (150 options) | 87.0 | n/a | 77.8 | 66.8 |
Long inputs
We measured lookups in order ledgers from 16K to 1M tokens, with the questions about one order placed at a random depth.
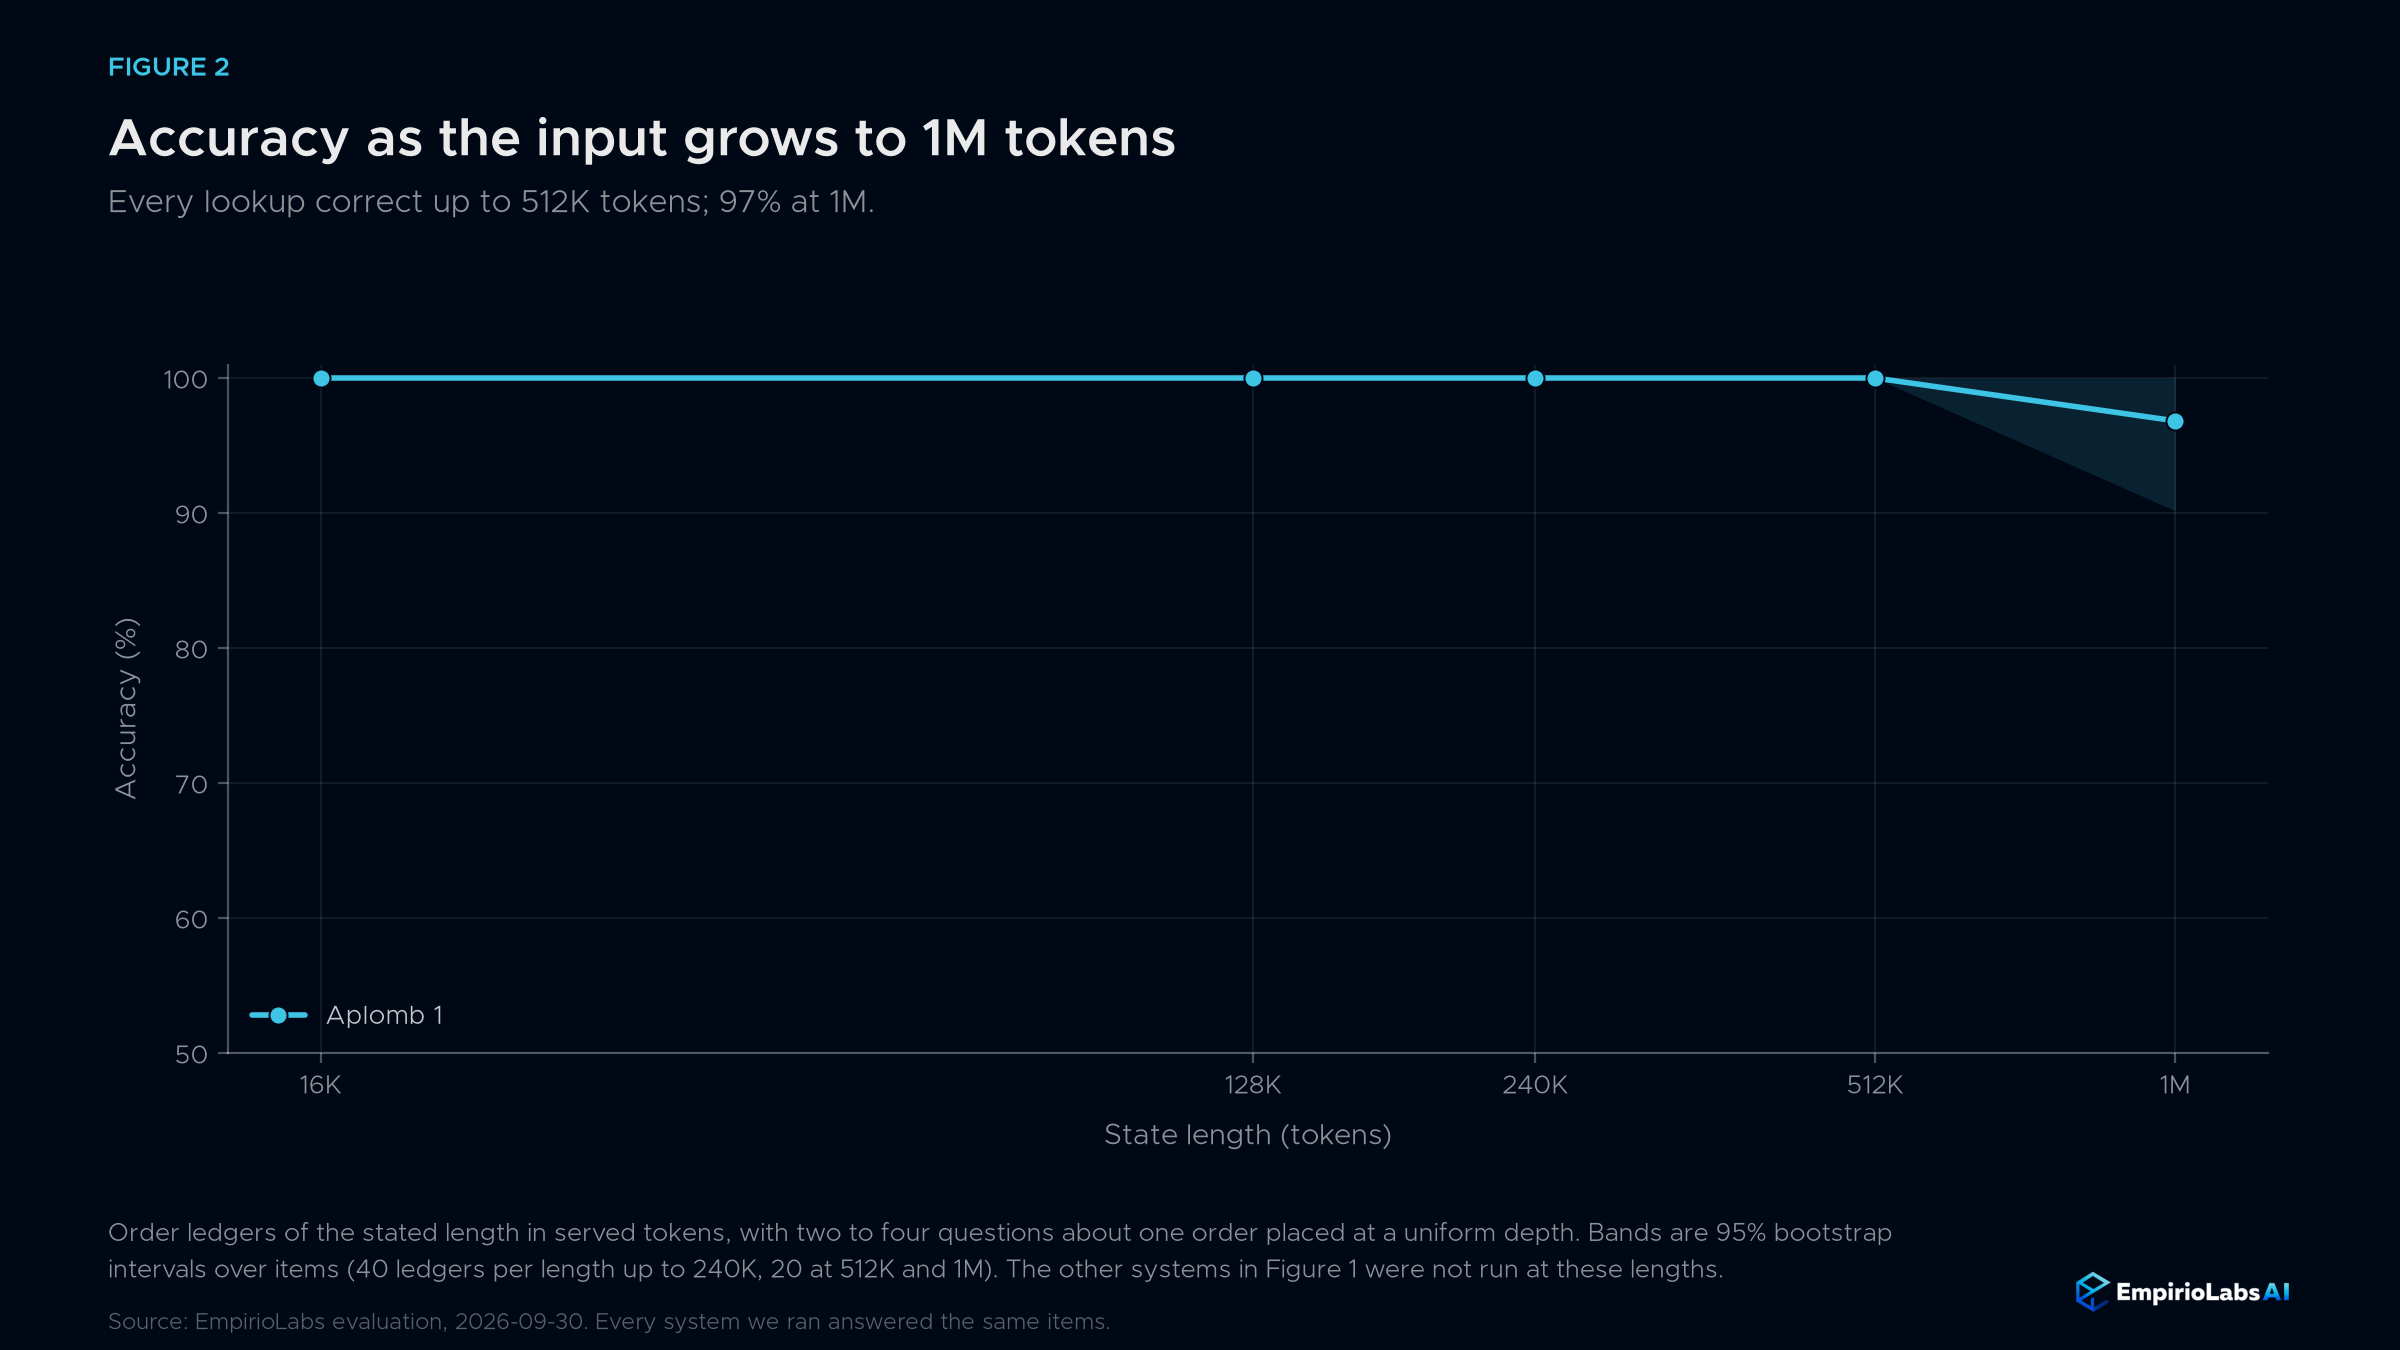
| Input length (tokens) | 16K | 128K | 240K | 512K | 1M |
|---|---|---|---|---|---|
| Aplomb 1 | 100.0 | 100.0 | 100.0 | 100.0 | 96.8 |
Long documents in seconds
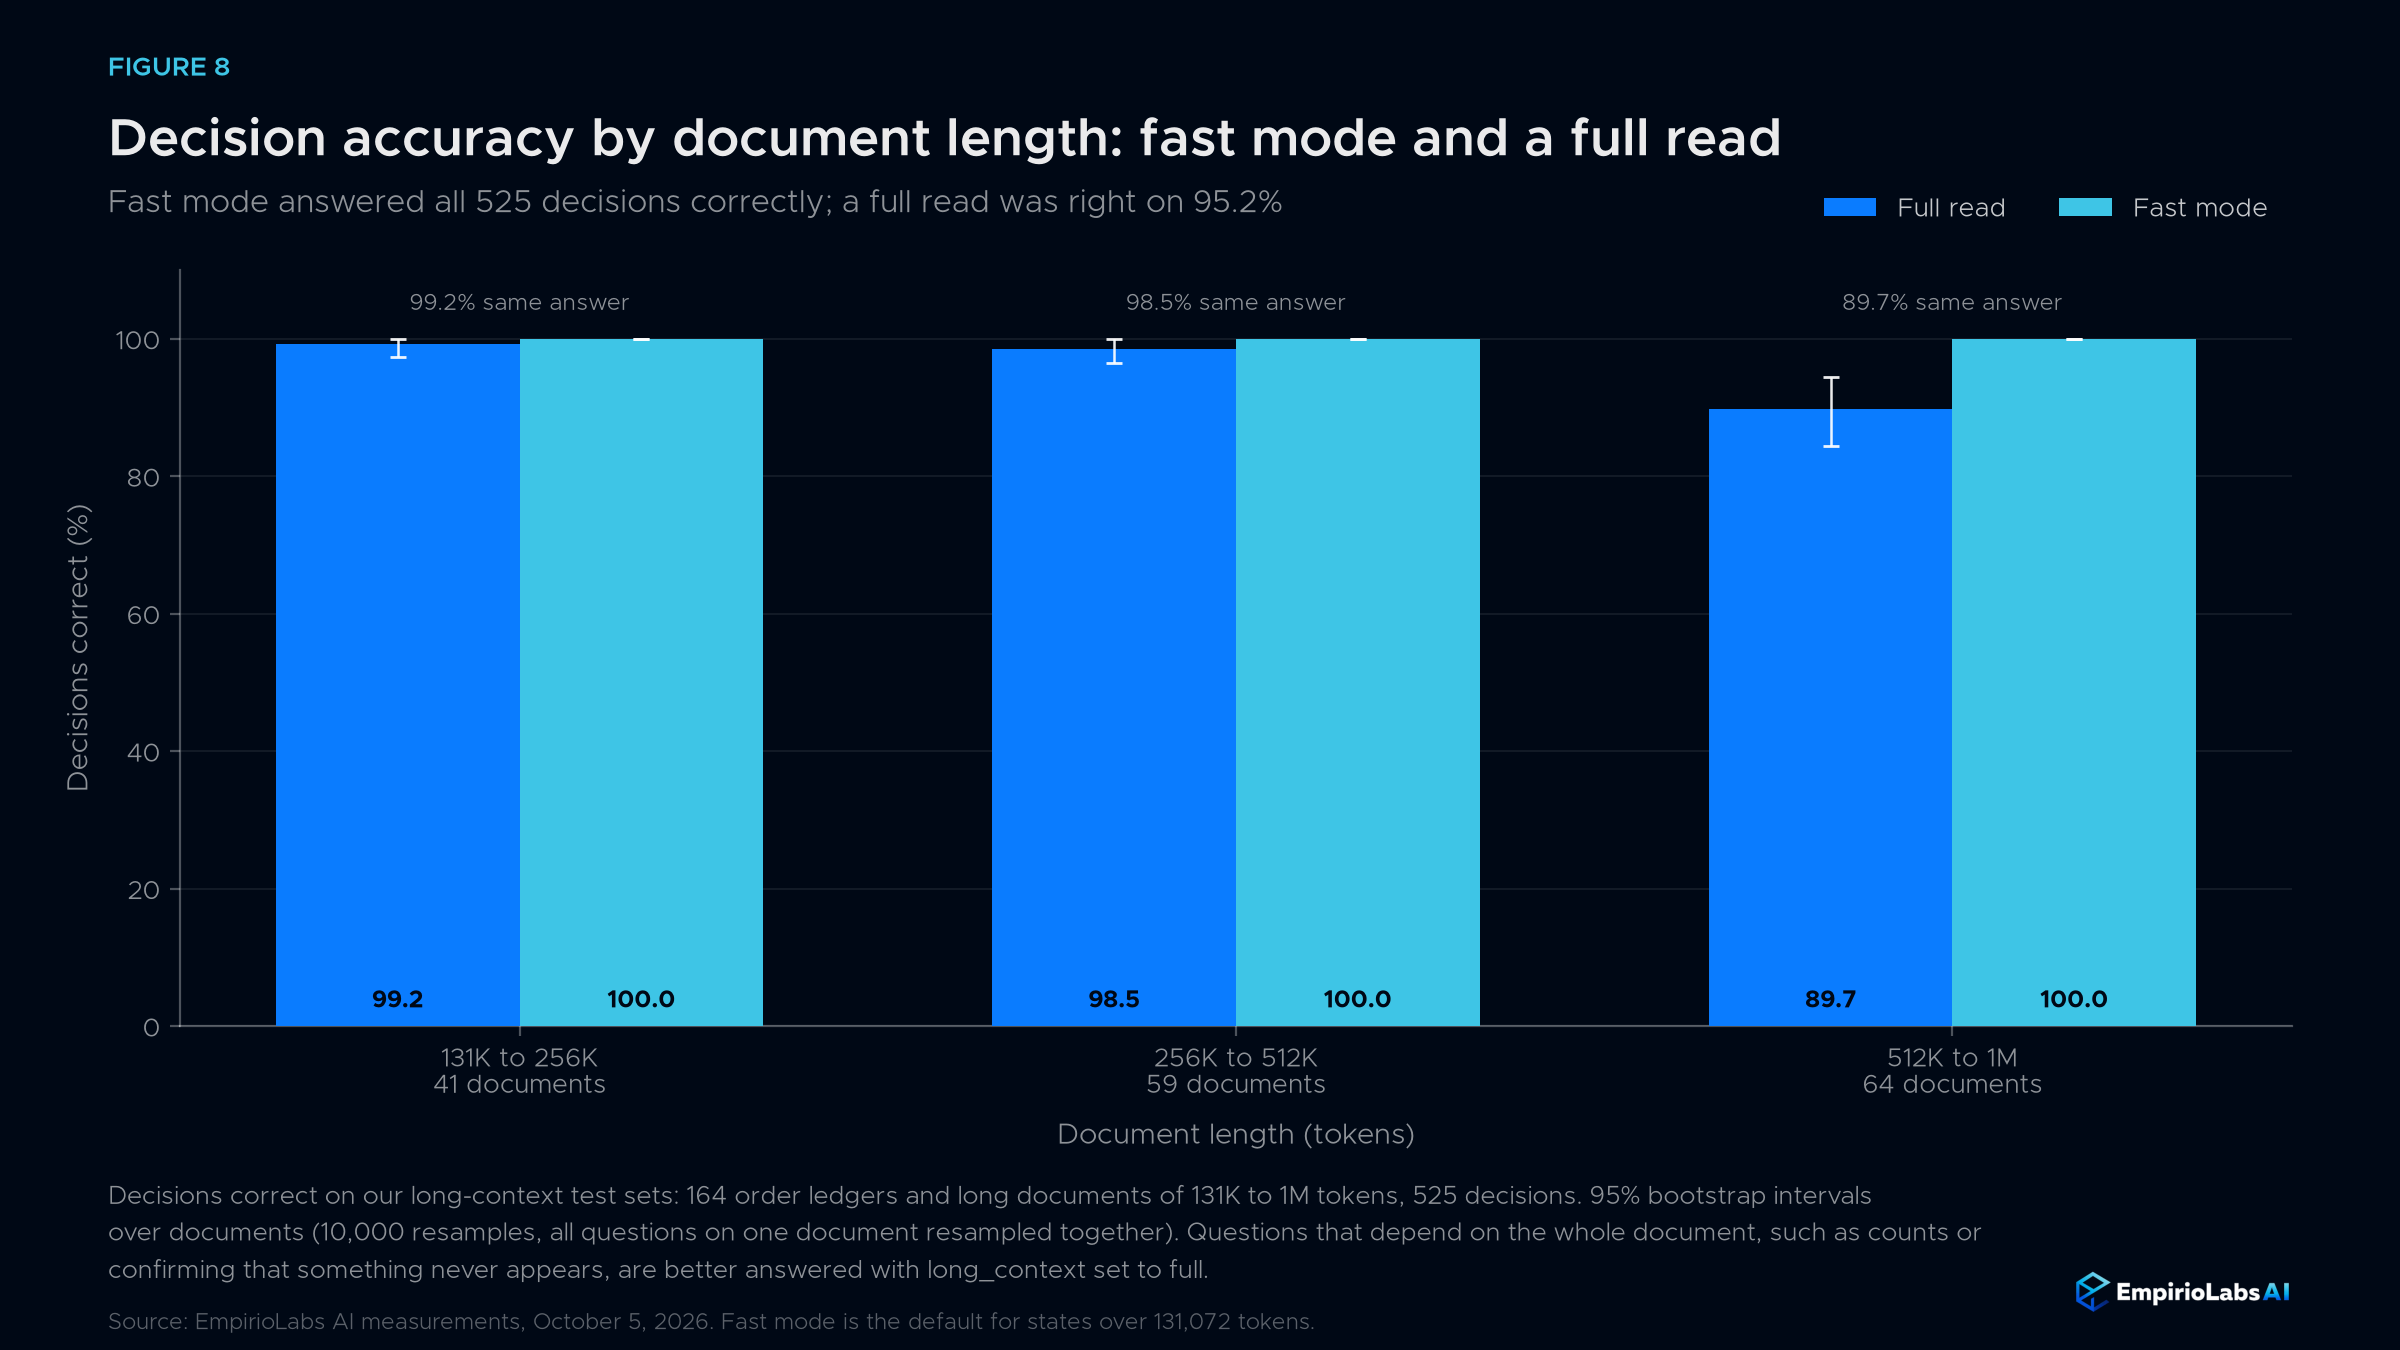
On the EmpirioLabs API and in the Playground, a state longer than 131,072 tokens is read in fast long-context mode by default. A 1M-token document takes about 3 seconds instead of about 111 seconds read in full, and on our long-context test sets fast mode answered all 525 decisions correctly, against 95.2% for a full read.
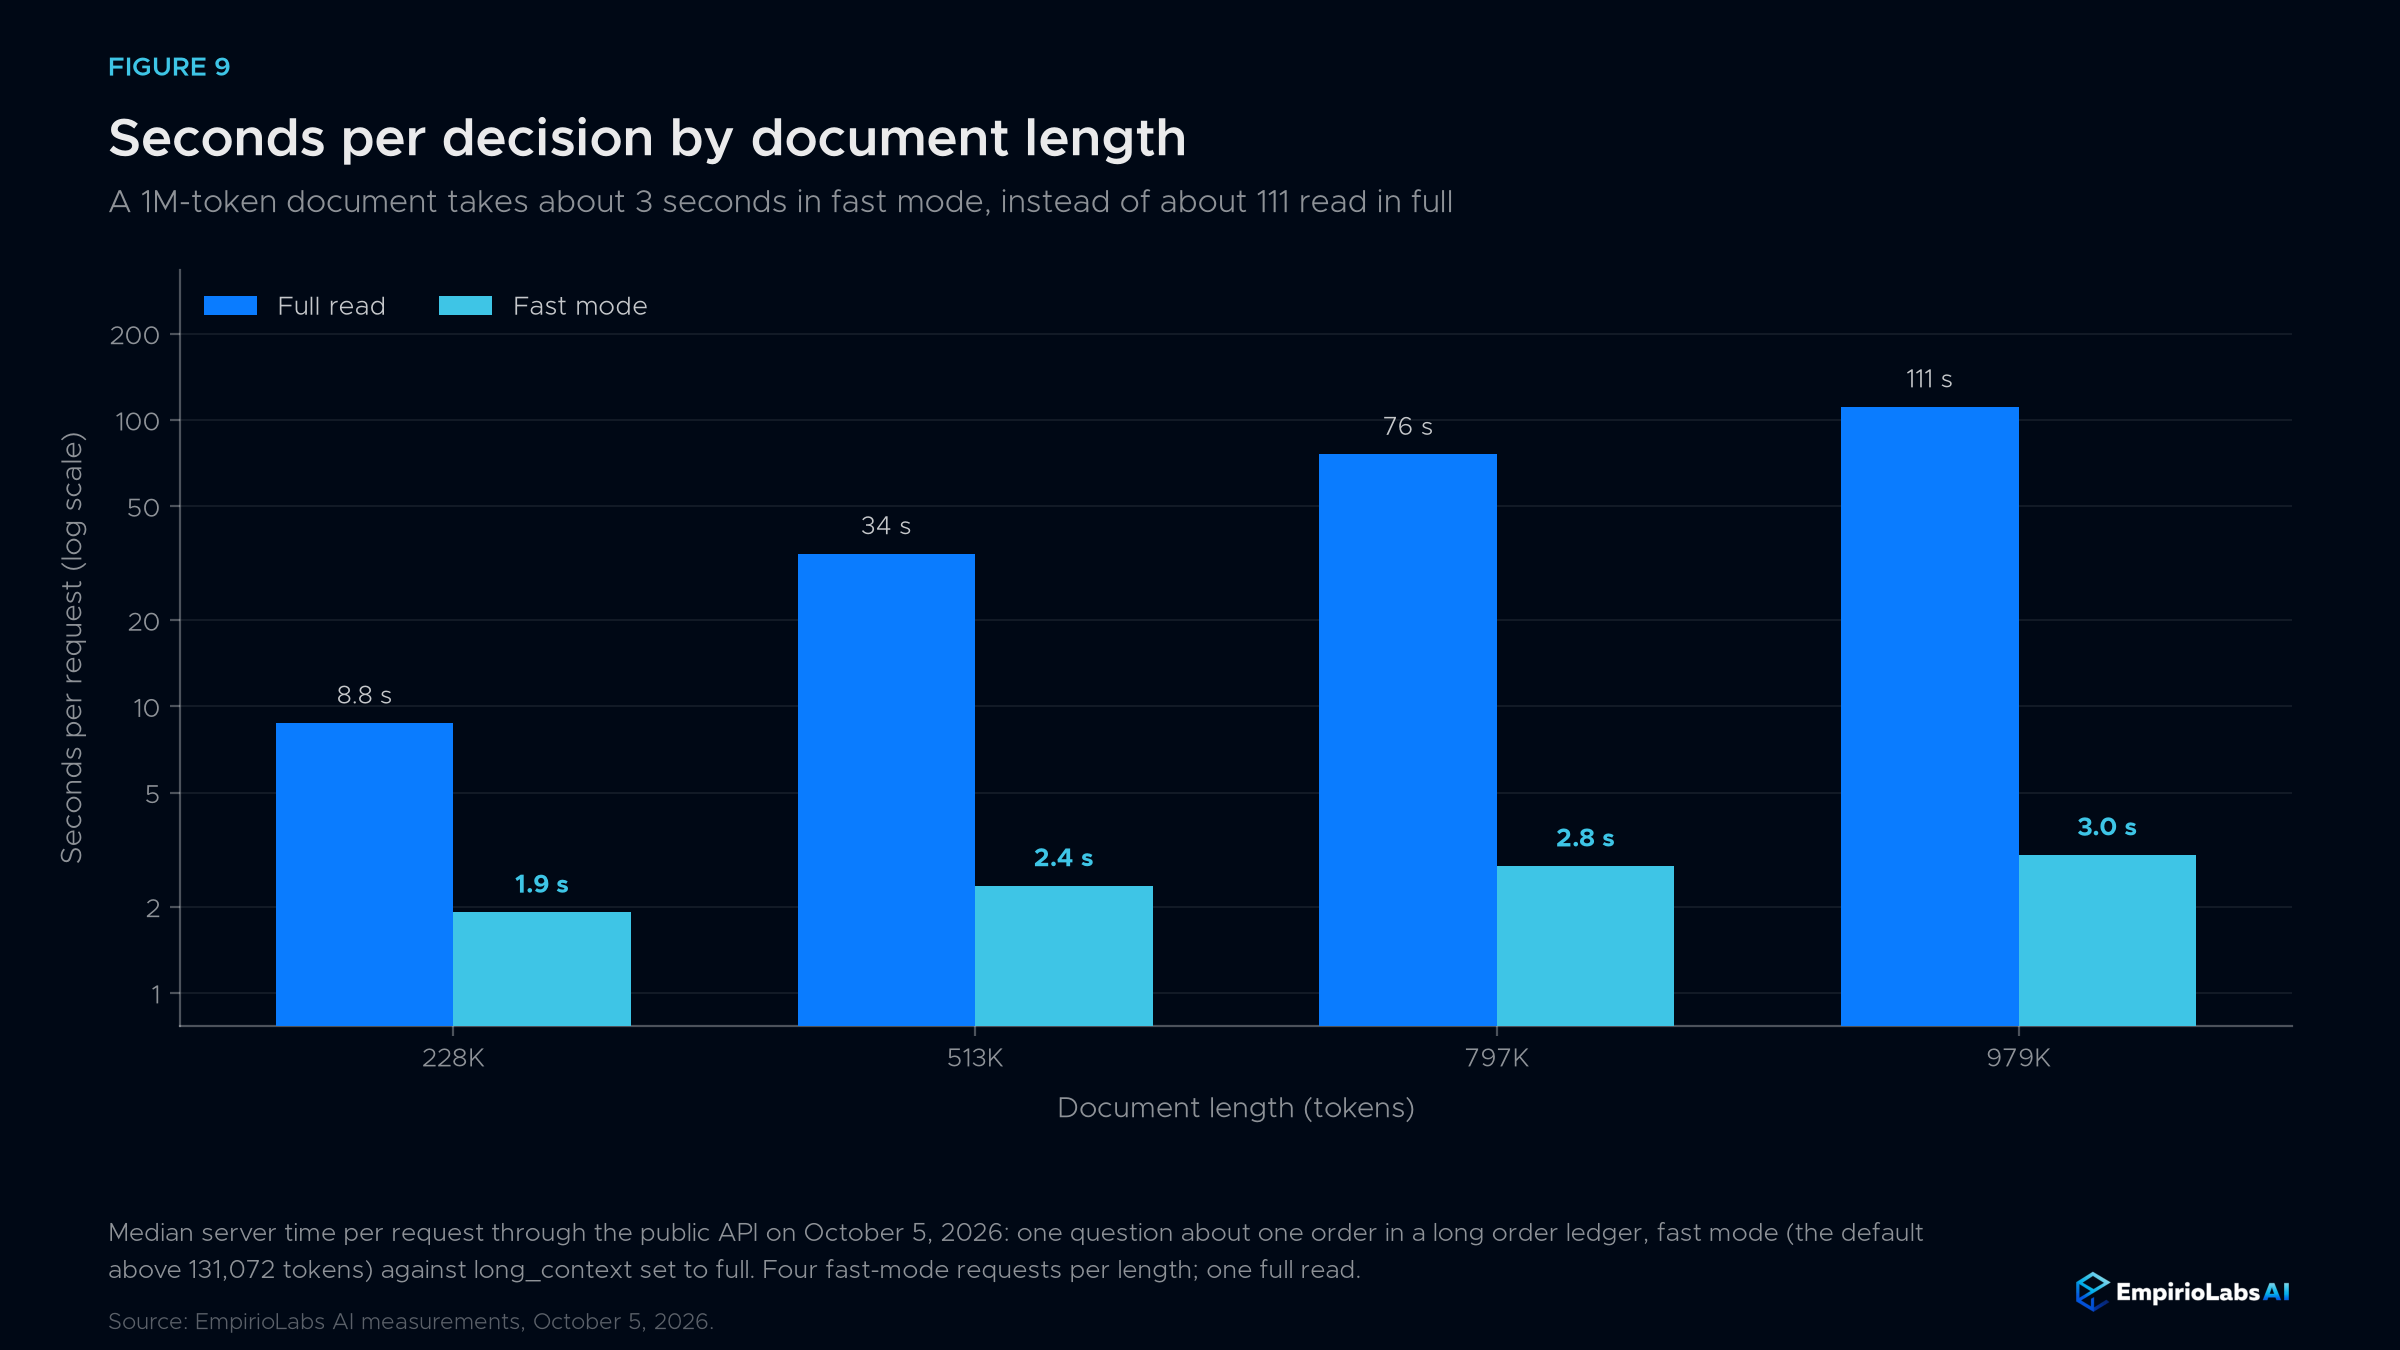
| Document length (tokens) | 228K | 513K | 797K | 979K |
|---|---|---|---|---|
| Fast mode | 1.9 s | 2.4 s | 2.8 s | 3.0 s |
| Full read | 8.8 s | 34 s | 76 s | 111 s |
Send "long_context": "full" to read every token. A full read is the better choice when an answer depends on the whole document, such as a count, the overall tone, or confirming that something never appears: on 24 documents built to test those questions, fast mode was right on 50% of decisions and a full read on 61%. The response's long_context field says which mode was used, and usage counts the whole state in both modes. Fast long-context mode is available only on the EmpirioLabs API and in the Playground; the open weights read every token.
Calibration
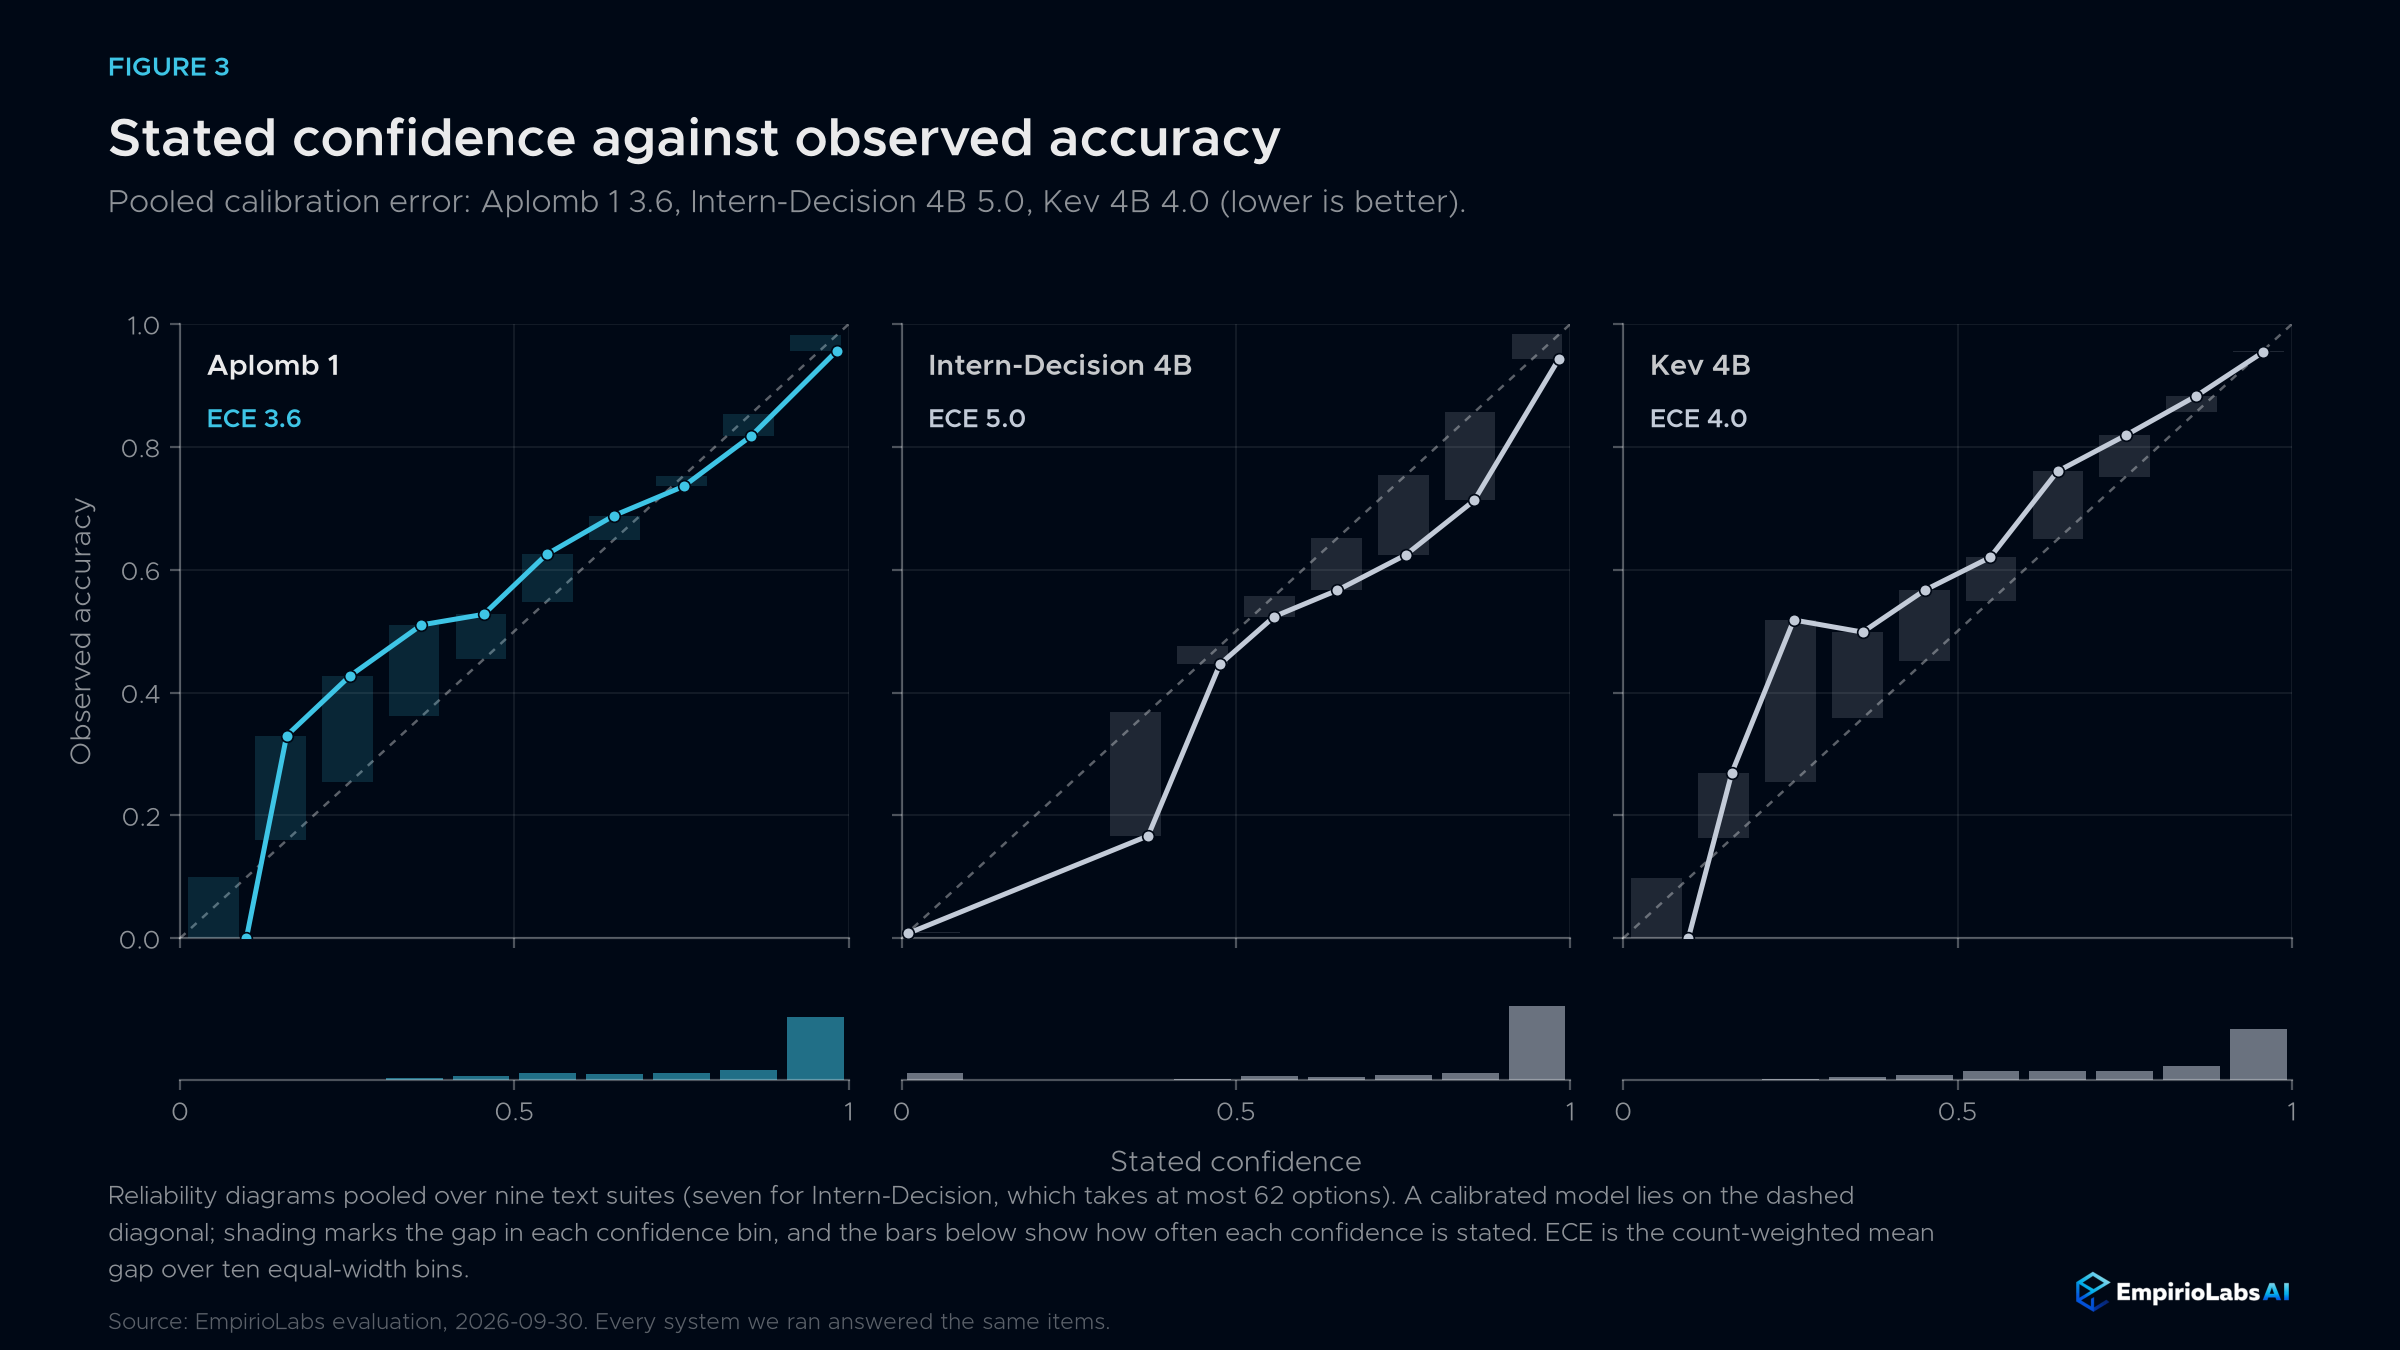
A probability is only useful if it means what it says. Across nine text suites, Aplomb 1's stated confidence tracks how often it is right: its pooled calibration error is 3.6, against 5.0 for Intern-Decision 4B and 4.0 for Kev 4B (lower is better).
Images, video and audio
| Benchmark (first 500 items) | Aplomb 1 | Intern-Decision 4B | OmniJev 4B |
|---|---|---|---|
| POPE | 89.0 | 89.2 | 88.4 |
| MMStar | 68.6 | 65.2 | 64.4 |
| AI2D | 87.0 | 81.0 | 83.4 |
| MMMU | 57.2 | 57.0 | 56.0 |
| HallusionBench | 79.8 | 79.4 | 71.2 |
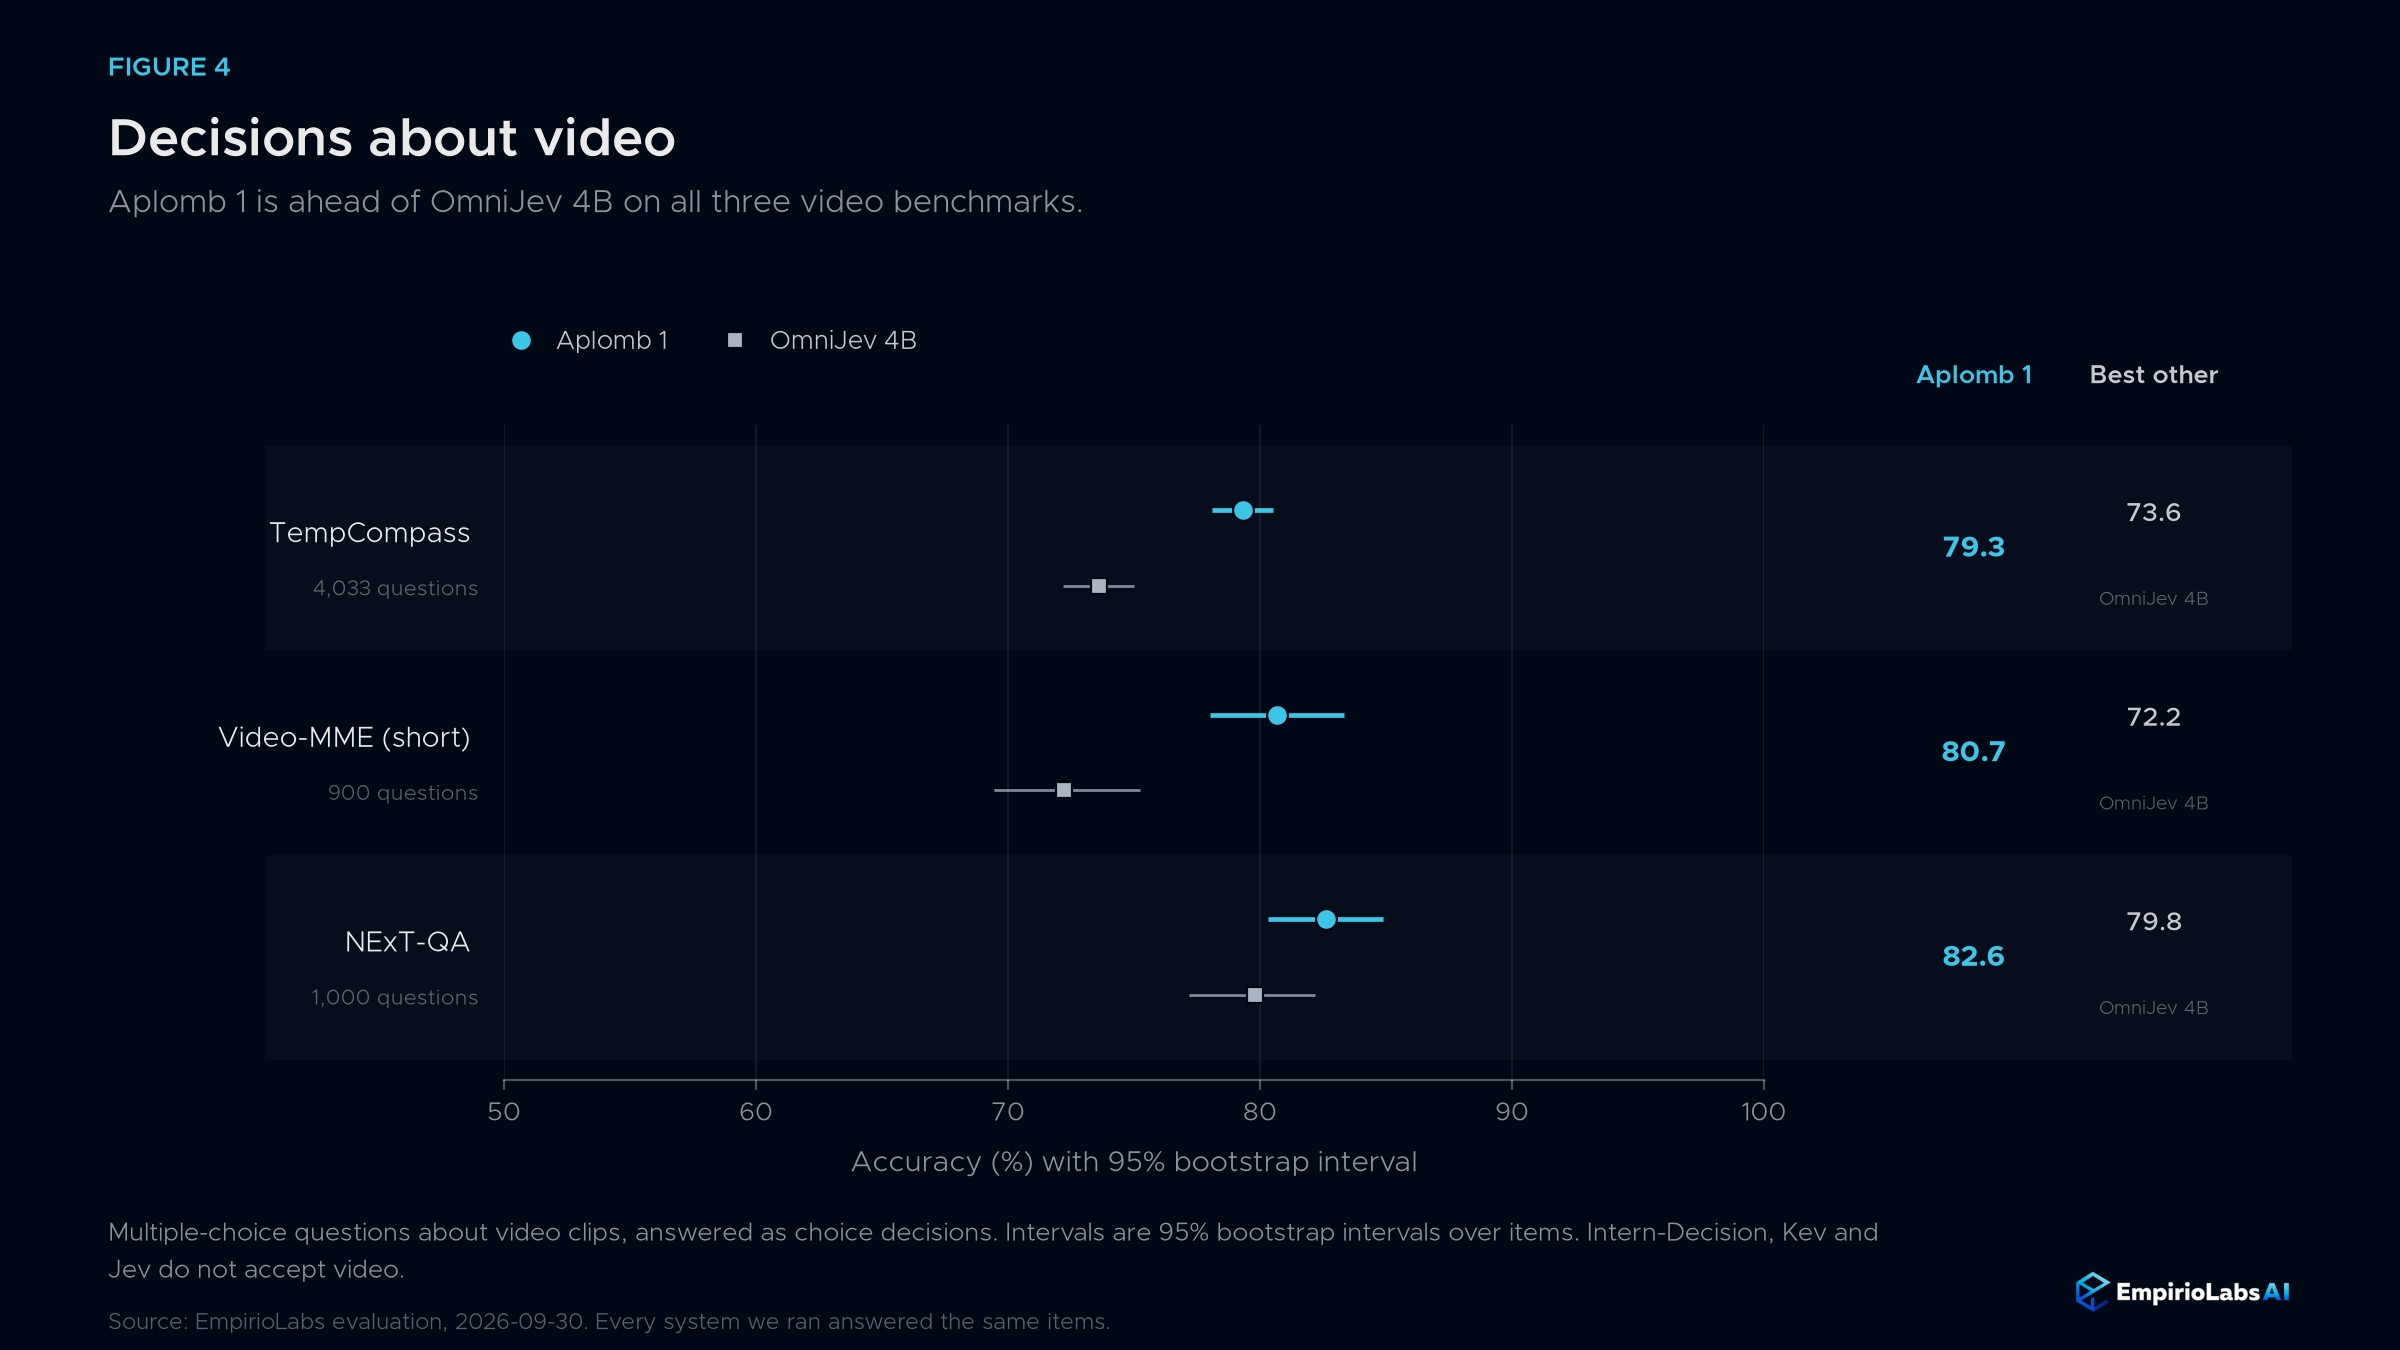
| Benchmark | Aplomb 1 | OmniJev 4B |
|---|---|---|
| TempCompass | 79.3 | 73.6 |
| Video-MME (short) | 80.7 | 72.2 |
| NExT-QA | 82.6 | 79.8 |
We added audio to Aplomb 1 ourselves; none of the other decision models above accepts it. It is strongest on speech and vocal sounds; environmental sounds and open-ended questions about audio are harder for it:
| Benchmark | Aplomb 1 |
|---|---|
| VocalSound (vocal sounds) | 90.0 |
| CREMA-D (emotion in speech) | 65.0 |
| ESC-50 (environmental sounds) | 8.4 |
| MMAU (audio questions) | 49.1 |
| MMSU (spoken language) | 43.3 |
51 languages
Aplomb 1 decides about text in many languages, not only English. On MASSIVE, each request to a voice assistant is written in one of 51 languages while the question and the 59 intent labels stay in English. Without any training on MASSIVE, Aplomb 1 averages 75.0% across the 51 languages when choosing among all 59 intents, 91.0% in English, and 70% or more in 39 of them.
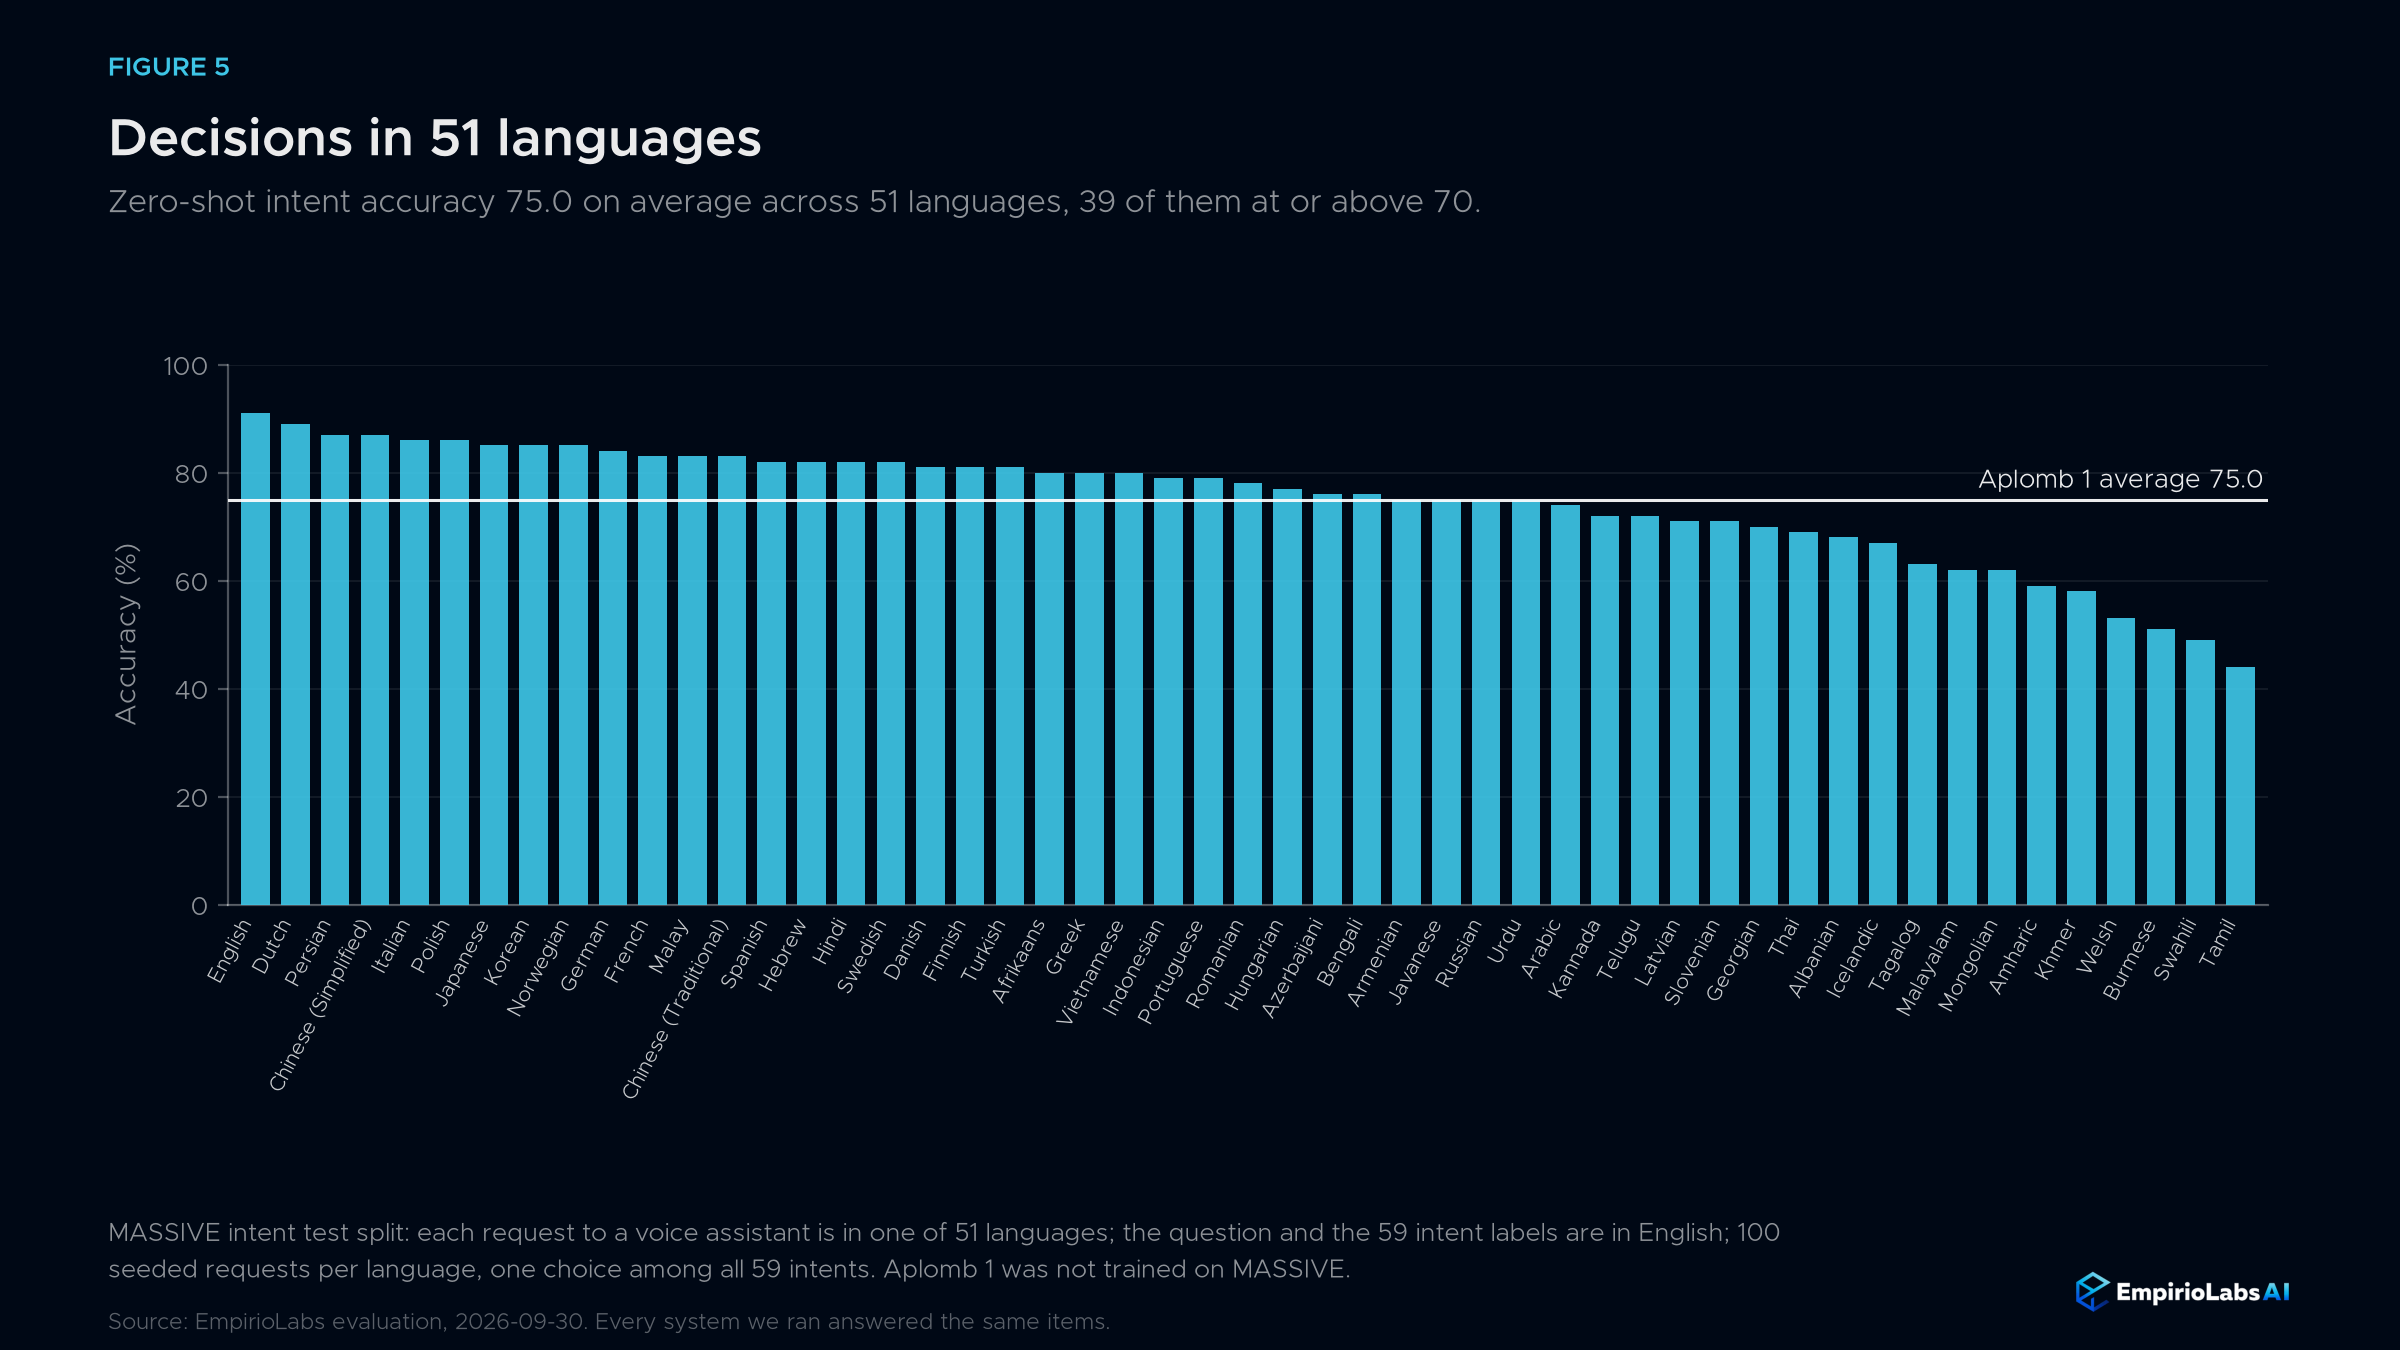
For reference, the Laya project reports 40.1% for its multilingual model across the same 51 languages when choosing among 20 intents, and the JevK5 project reports 73.8% in English with all 60 intents.
Decision Index
Decision Index 0.2.1 averages 38 public benchmarks in five areas: knowledge and reasoning, language understanding, retrieval and classification, tools and automation, and arts and human taste. Each benchmark is chance-corrected, so 0 means random guessing and 100 means perfect.
We ran the official kit on Aplomb 1 on October 5, 2026, and it answered all 150,317 scoreable requests. Aplomb 1 scores 44.86. This is our own run of the kit, not an entry on the published board.
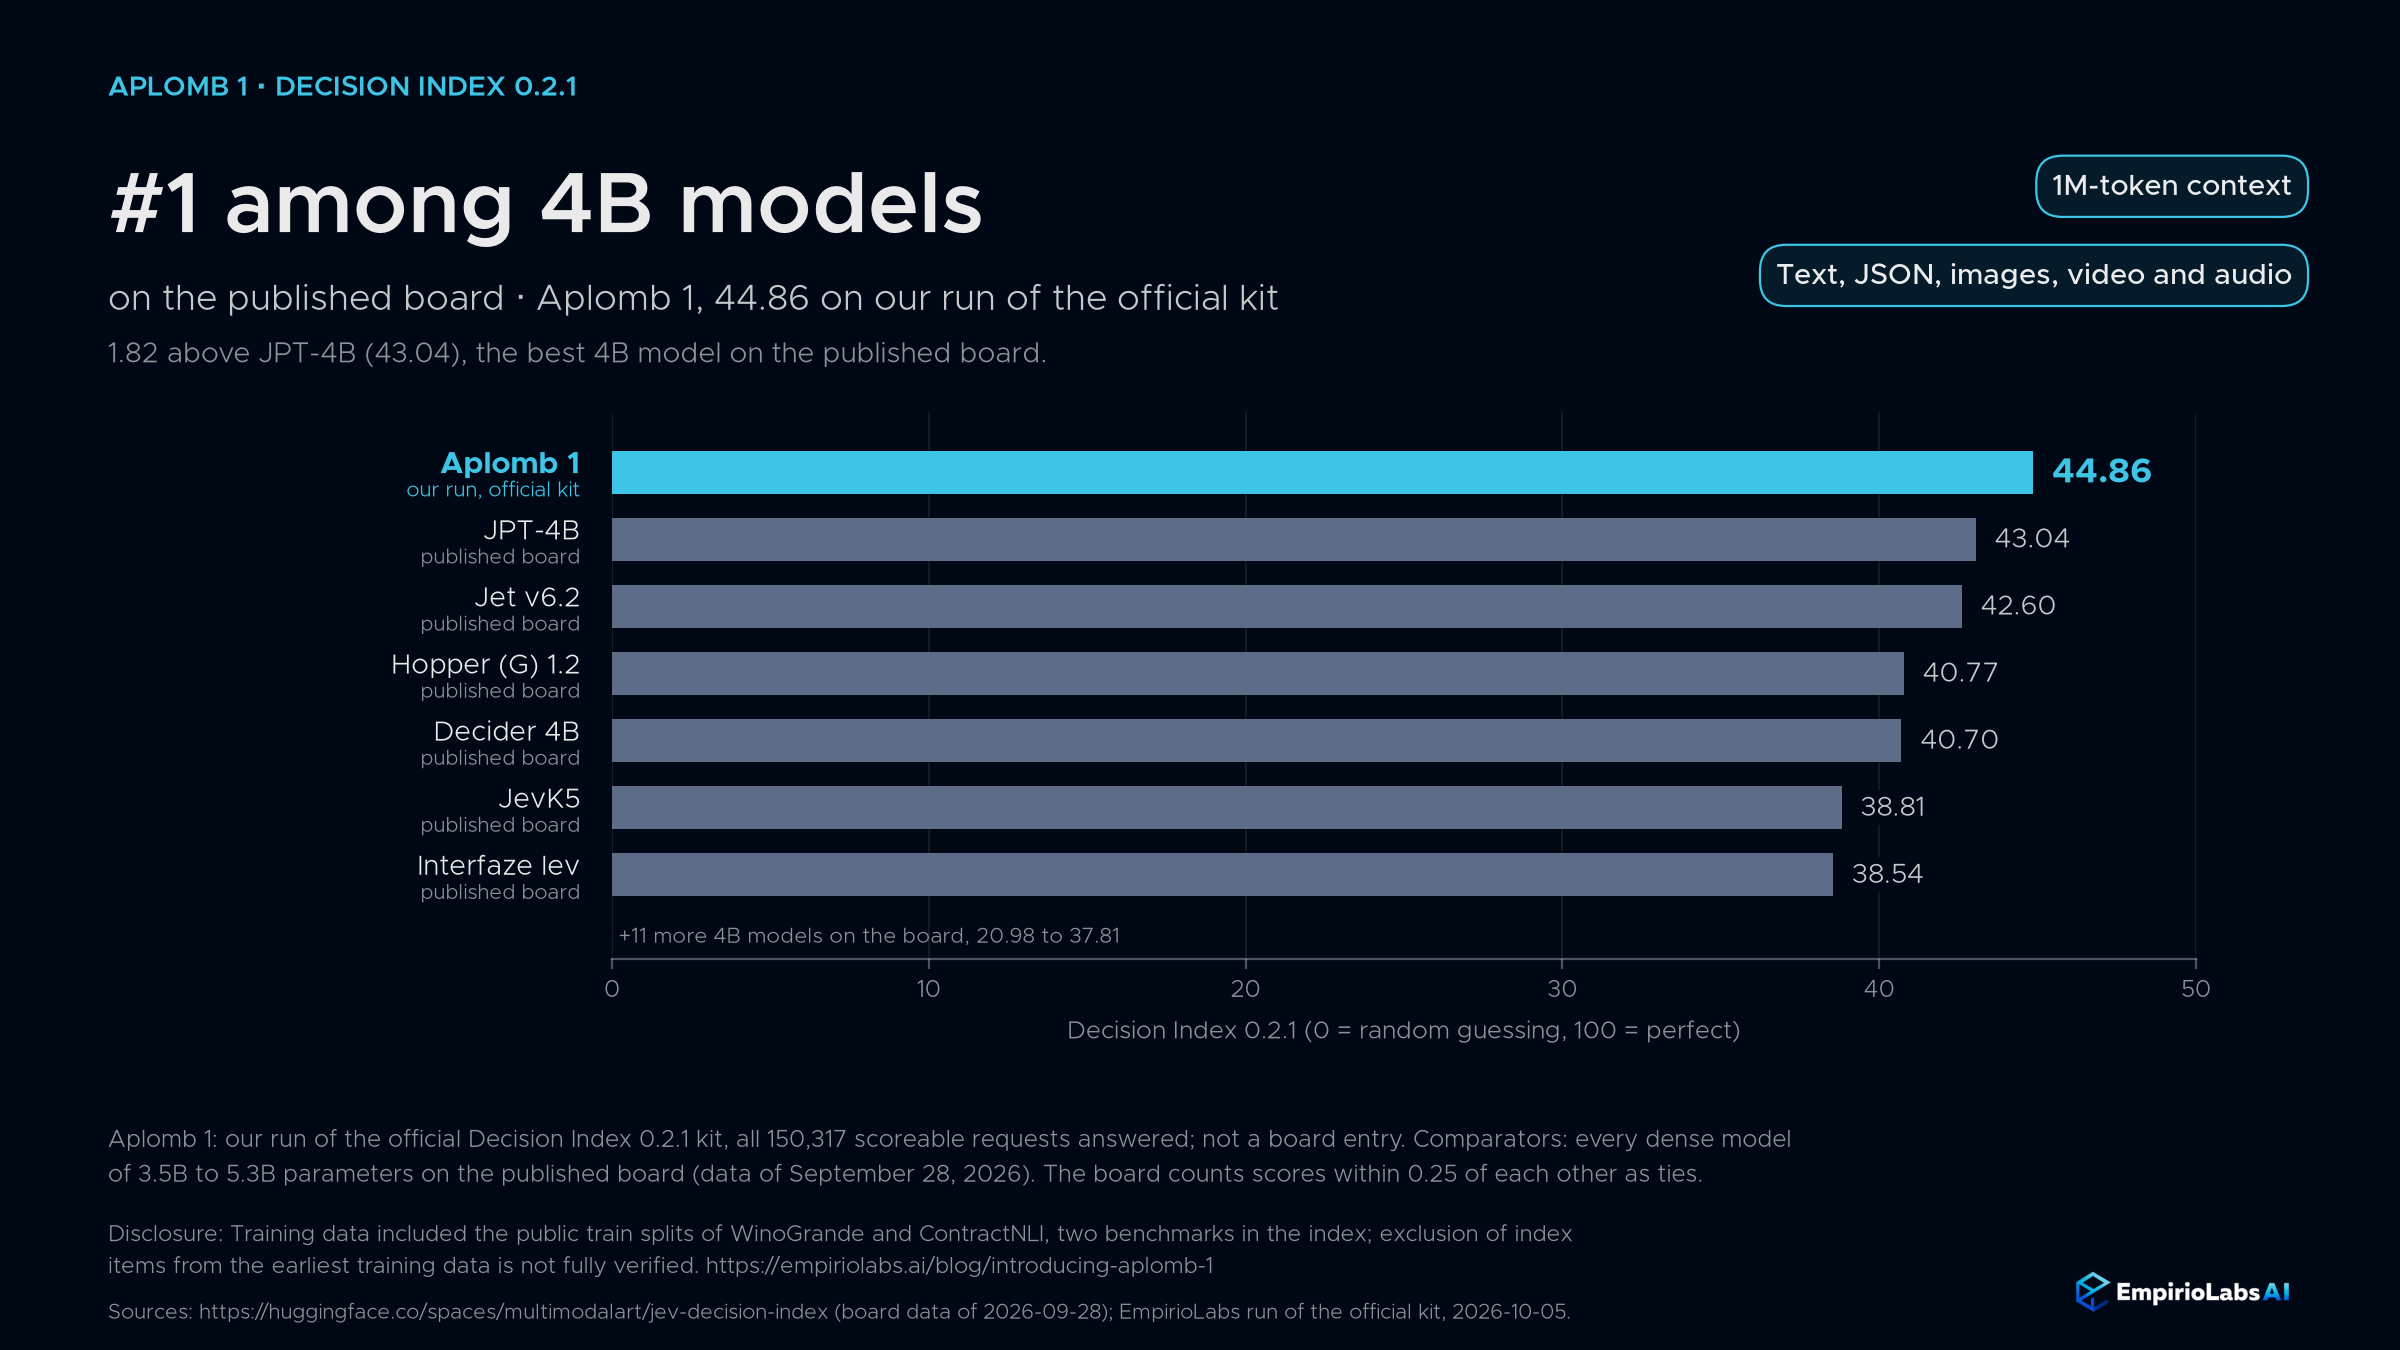
As of October 6, 2026, Aplomb 1 is #1 among 4B models on the published board, and #1 among models up to 5.3B parameters on 8 of the 38 benchmarks, including MMLU-Pro, GPQA Diamond and BBH. On the published board (data of September 28, 2026), the highest score for a 4B model is JPT-4B's 43.04, 1.82 below Aplomb 1.
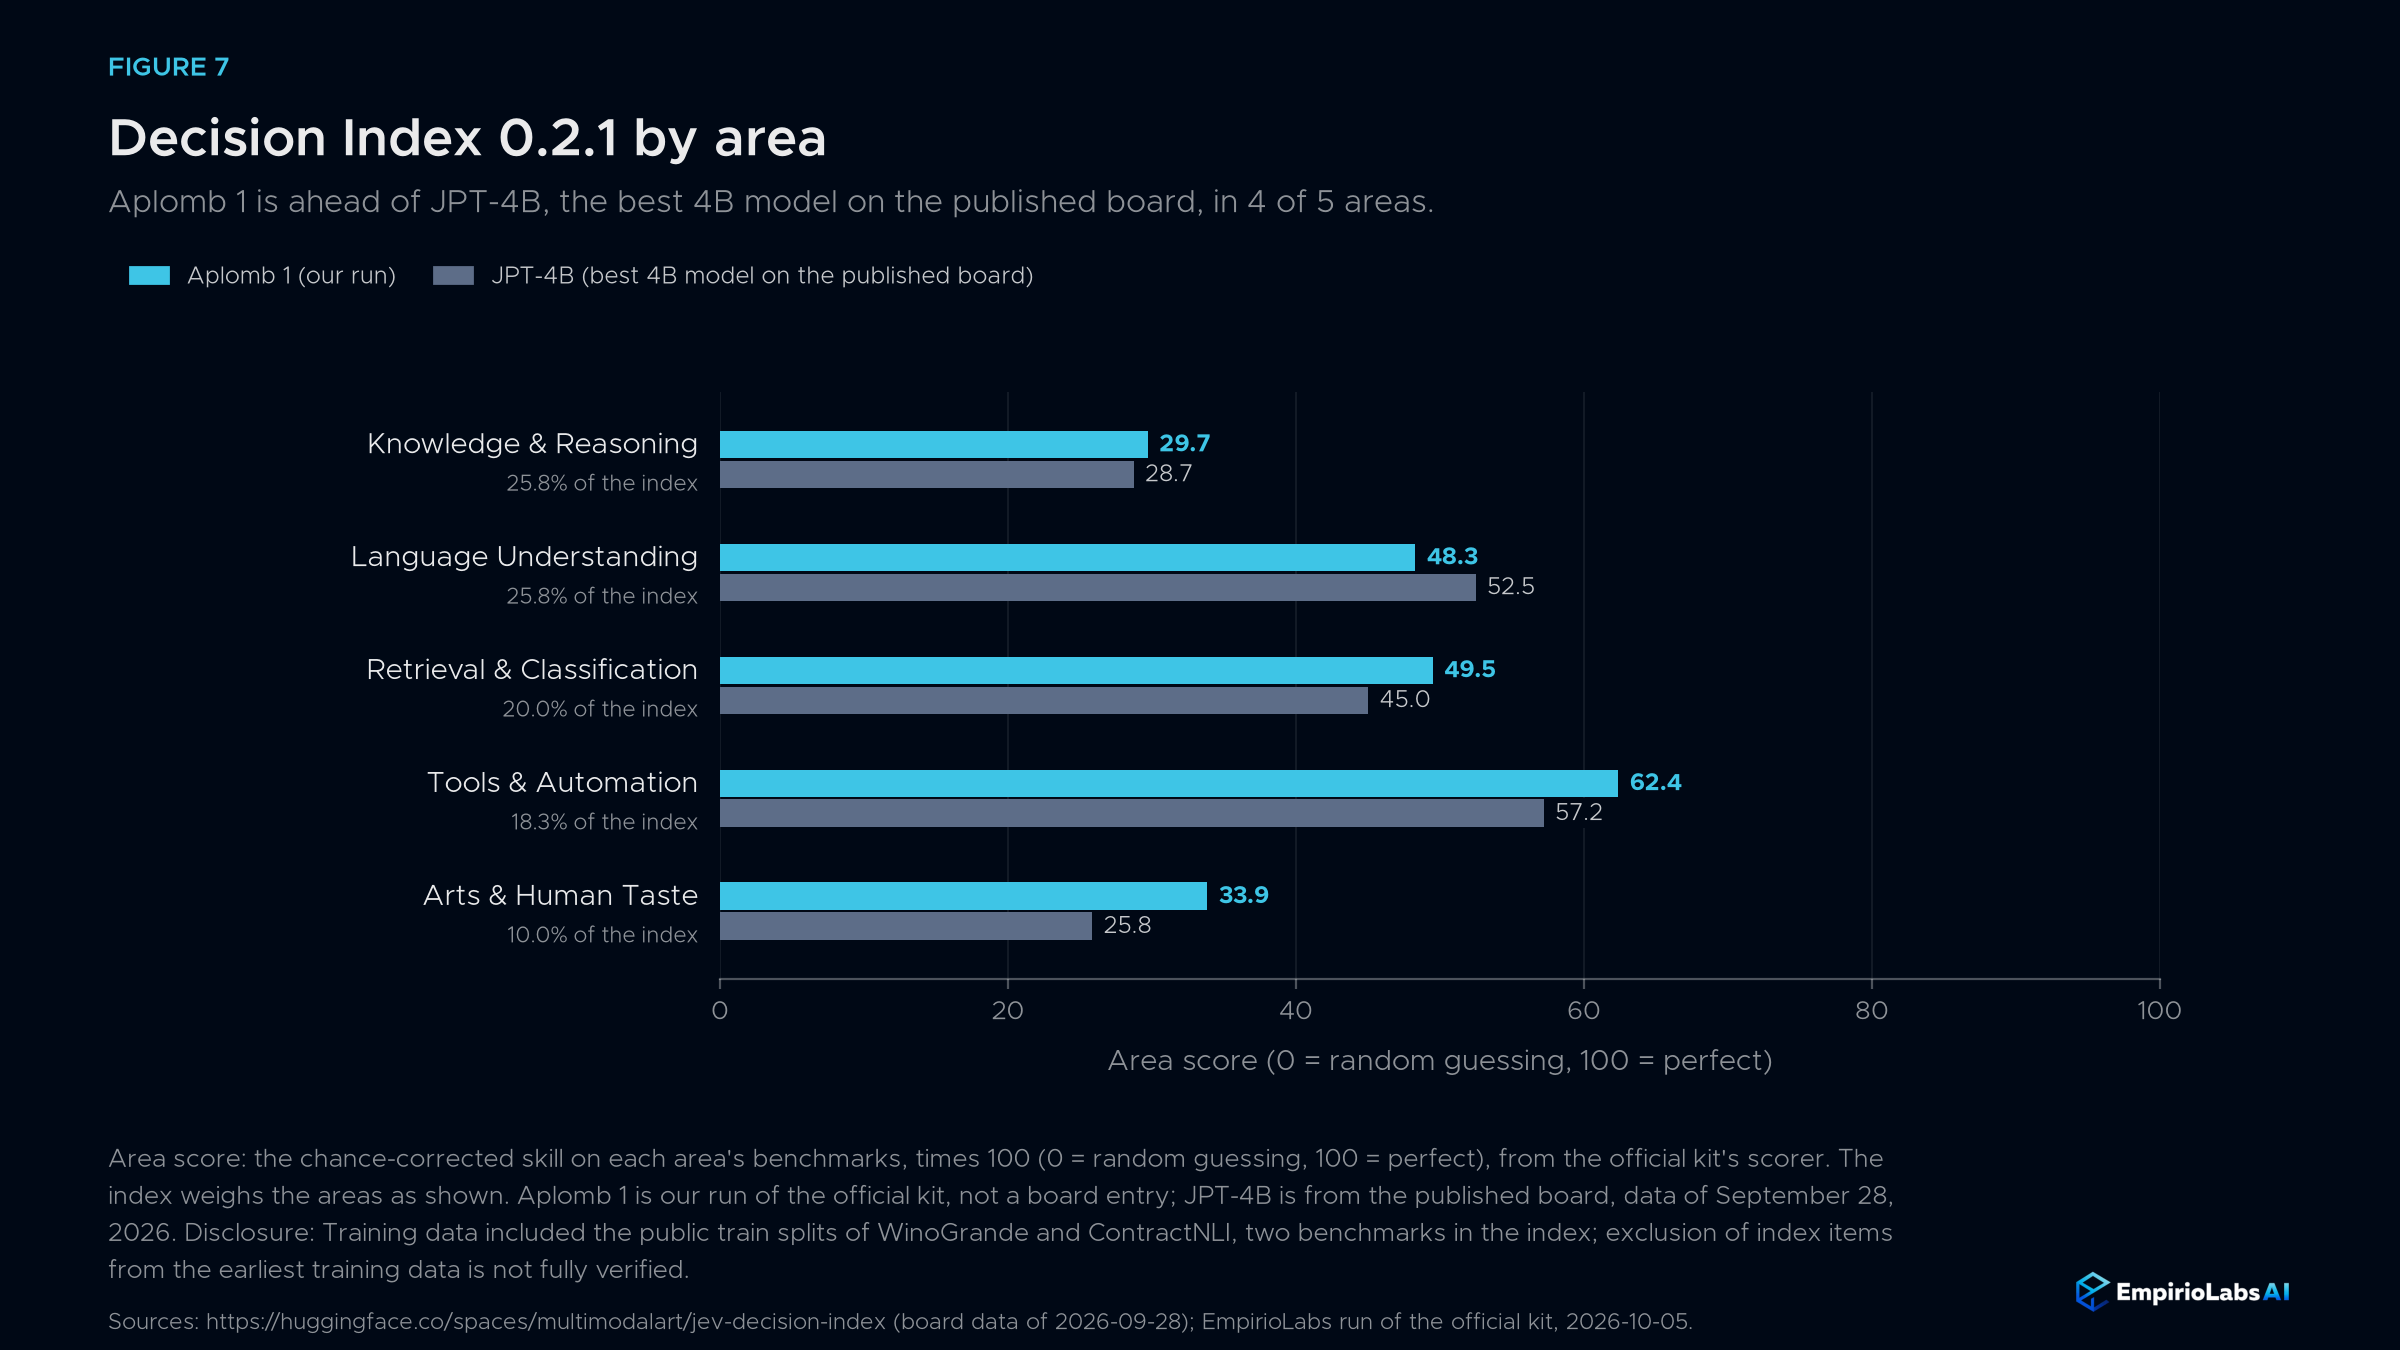
By area, Aplomb 1 scores highest in tools and automation (62.4) and retrieval and classification (49.5). Compared with JPT-4B, it is ahead in four of the five areas and behind in language understanding (48.3 against 52.5).
Disclosure. Aplomb 1's training data included the public train splits of WinoGrande and ContractNLI, two of the 38 benchmarks in the index. We could not fully verify that index items were excluded from the earliest training data.
How it compares
What each decision model or API accepts and answers, from its own published documentation as of September 29, 2026, with prices as of October 6, 2026:
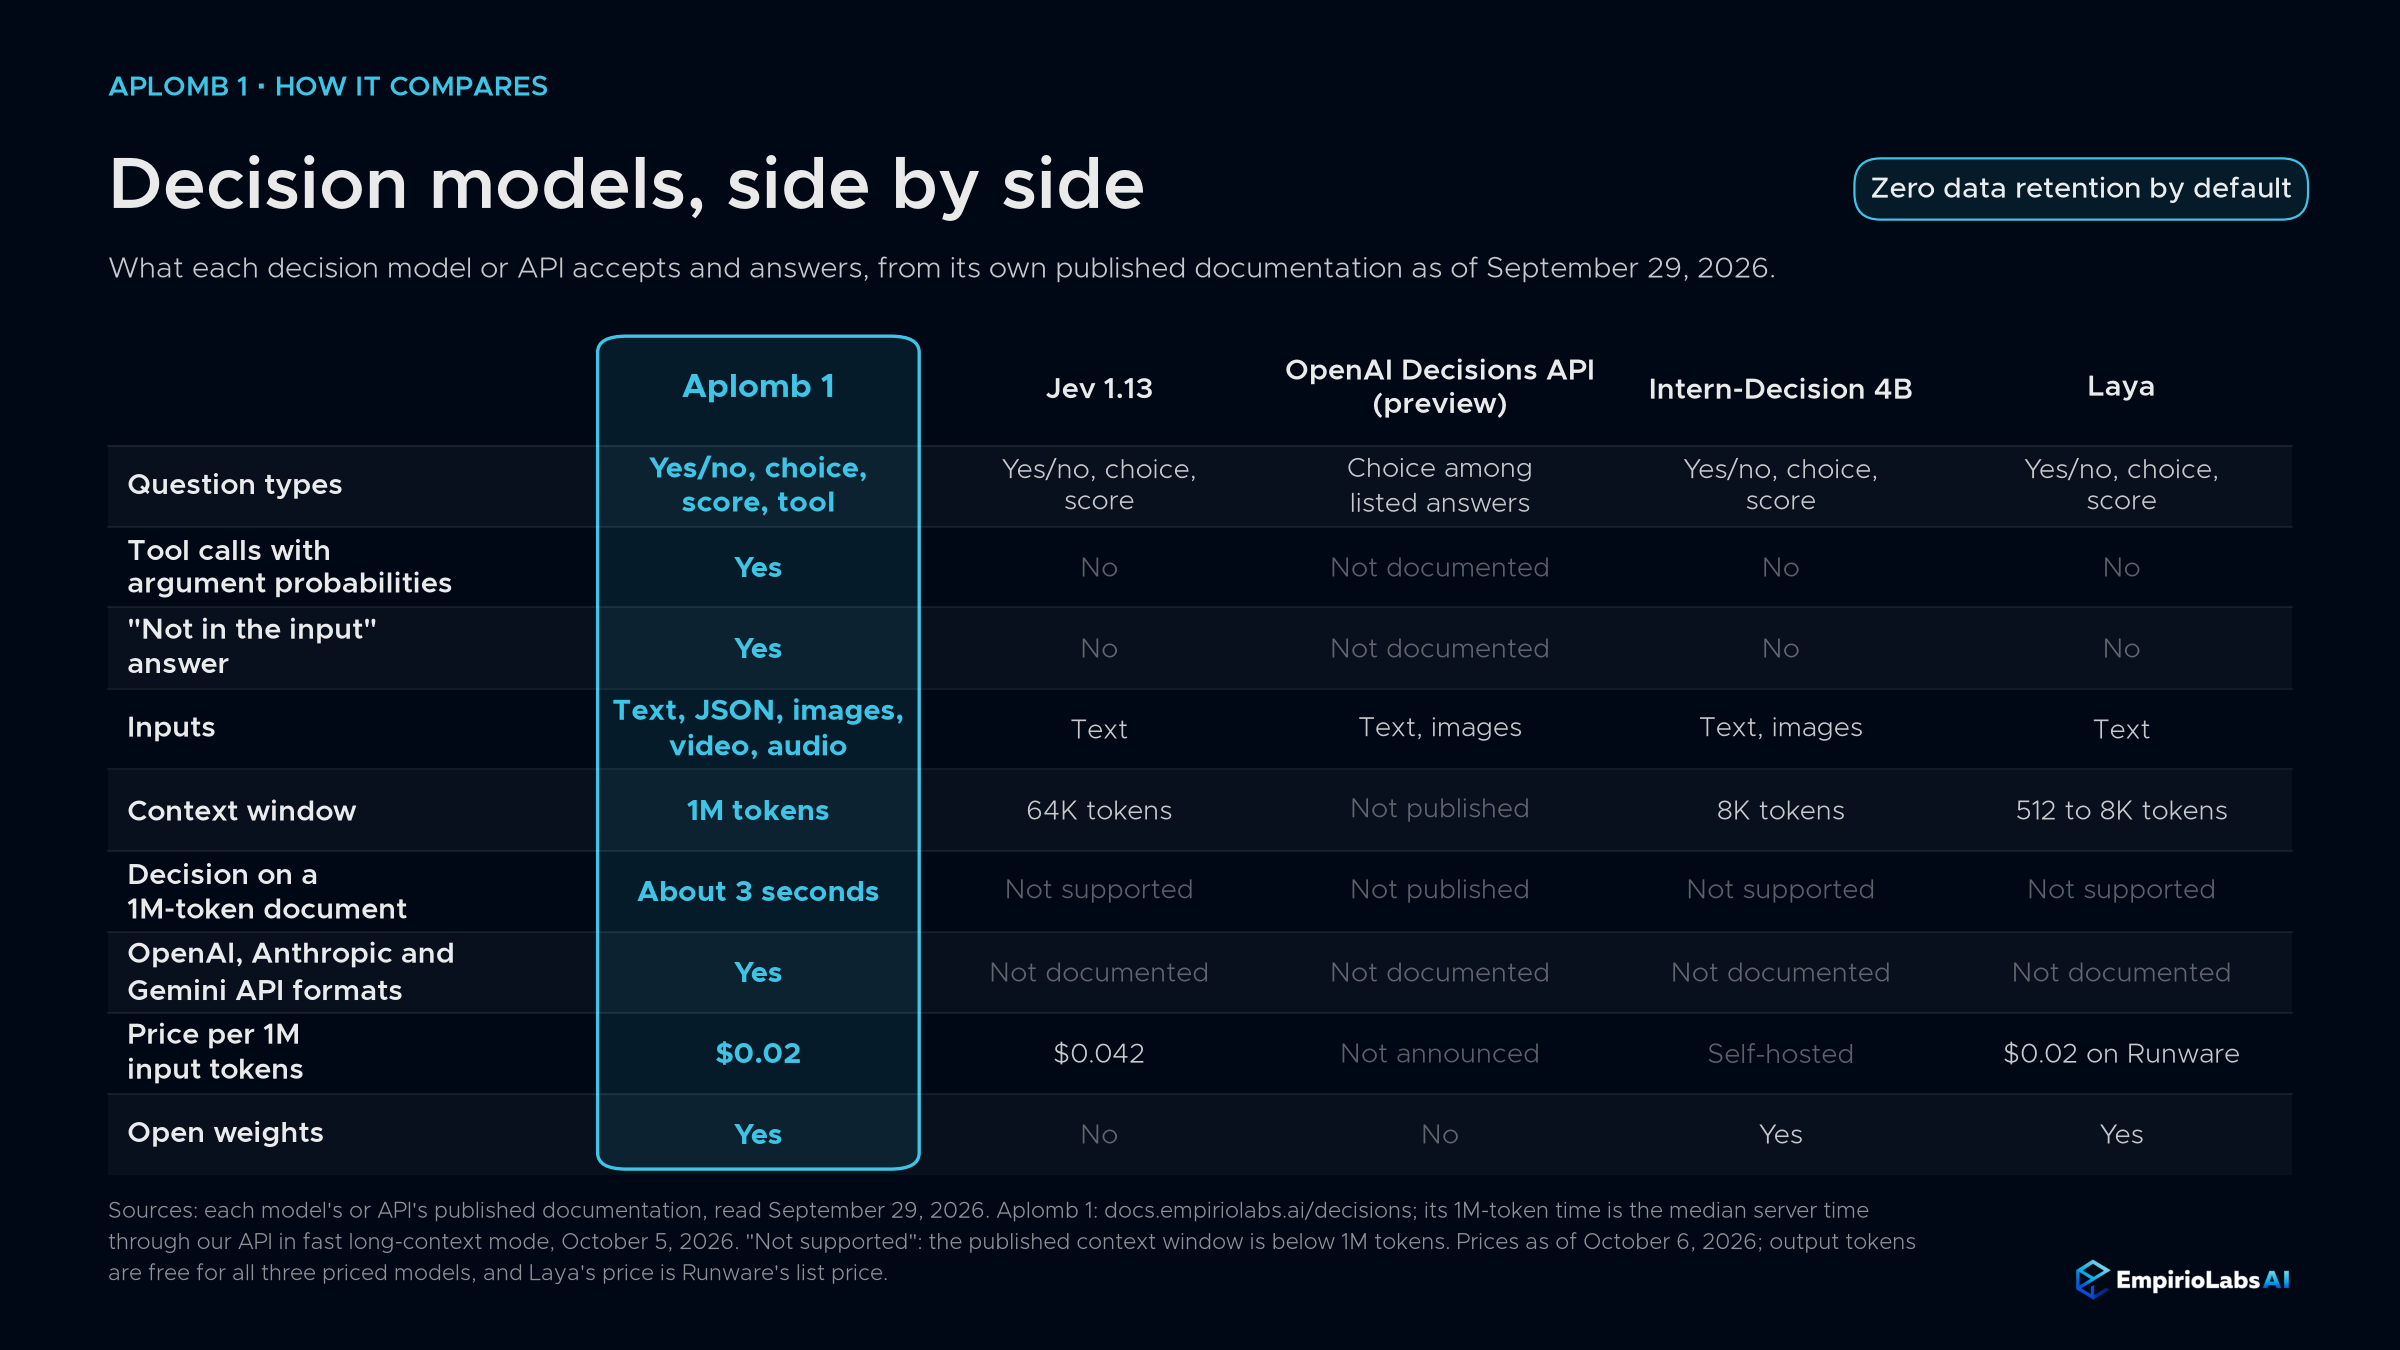
| Aplomb 1 | Jev 1.13 | OpenAI Decisions API (preview) | Intern-Decision 4B | Laya | |
|---|---|---|---|---|---|
| Question types | Yes or no, choice, score, tool | Yes or no, choice, score | Choice among listed answers | Yes or no, choice, score | Yes or no, choice, score |
| Tool selection with argument probabilities | Yes | No | Not documented | No | No |
| Not in the state answer | Yes | No | Not documented | No | No |
| Inputs | Text, JSON, images, video, audio | Text | Text, images | Text, images | Text |
| Window | 1,000,000 tokens | 64K tokens | Not published | 8,192 tokens | 512 to 8,192 tokens |
| Price per 1M input tokens | $0.02 | $0.042 | Not announced | Self-hosted | $0.02 on Runware |
| Open weights | Yes | No | No | Yes | Yes |
Speed and billing
Aplomb 1 runs on EmpirioLabs' own inference runtime for decision models. A short question takes about 15 ms of model time, a question with an image about 35 ms, a 15,000-token document about 0.3 seconds, and a 1M-token state about 3 seconds in fast long-context mode, the default above 131,072 tokens, or about 111 seconds read in full.
You pay for input tokens only: the state once per request and each question's own text, never a prompt template. Output tokens are always zero. The current rate is on the model page and the pricing page.
Zero data retention is on by default: we do not retain the content of your requests or responses.
Open weights
Aplomb 1 is built on Qwen3.5-4B. We extended its window from 262K to 1M tokens, added audio input with the audio encoder of Qwen3-Omni, added our own decision head, which returns every answer as calibrated probabilities instead of generated text, and trained the model for decisions, including tool selection and the not-in-the-input answer. For the API and the Playground, we built and optimized our own inference runtime.
The weights and a reference script for running them yourself are at huggingface.co/empiriolabsai/aplomb-1. The script's answers can differ slightly from the API's.
Research, evaluation, personal use and internal use by organizations with annual revenue under US$1 million are free under the EmpirioLabs Model License; hosting Aplomb 1 as a service or shipping it in a product sold to others needs a commercial license.
Get started
curl https://api.empiriolabs.ai/v1/decisions \
  -H "Authorization: Bearer $EMPIRIOLABS_API_KEY" \
  -H "Content-Type: application/json" \
  -d '{
    "model": "aplomb-1",
    "state": {"order": {"id": "B-44120", "status": "shipped", "payment": "unpaid"}},
    "questions": {
      "paid": {"type": "noul", "instructions": "Has order B-44120 been paid?", "abstain": true},
      "carrier": {"type": "choice", "instructions": "Which carrier is delivering order B-44120?",
                  "criteria": {"ups": null, "fedex": null, "dhl": null}, "abstain": true}
    }
  }'
paid comes back as a confident no. carrier comes back with a high abstain probability, because the record does not name a carrier. The full schema, media input and limits are in the Decisions API guide. Aplomb 1 also accepts requests in the OpenAI, Anthropic and Gemini formats, so you can call it from their SDKs; the guide's chat formats section shows how a chat request maps to a decision. Try it without code in the Playground.
Acknowledgements
We built Aplomb 1 with help from our AI agent harness across data, training, evaluation and deployment. Thanks to the Qwen team for Qwen3.5 and Qwen3-Omni, which Aplomb 1 builds on, to Lambda for the GPUs we trained and serve it on, and to the NVIDIA Inception program, the Z.ai startup program and the StepFun startup program for their support.